• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

Server

Scalable Snapshots demo with the vSAN 8.0 Express Storage Architecture

Duncan Epping · Sep 5, 2023 ·

Starting with vSAN 8 a brand new architecture was introduced called “Express Storage Architecture”. Over the last year or so a lot of information has been shared about ESA and the benefits of ESA. One of the things which ESA introduces is much-improved snapshot scalability.

With vSAN OSA, and with VMFS, when you create a snapshot you typically immediately see a performance degradation. This is because both VMFS and vSAN OSA still operate using the redo-log based snapshot mechanism. This means that with vSAN OSA when you create a snapshot a new object is created and writes are re-directed. It also means that reads will be coming from various files, if you have one or more snapshots. This mechanism is, unfortunately, not very effective. Let me borrow a diagram that is part of a post John Nicholson wrote to demonstrate that old logic.
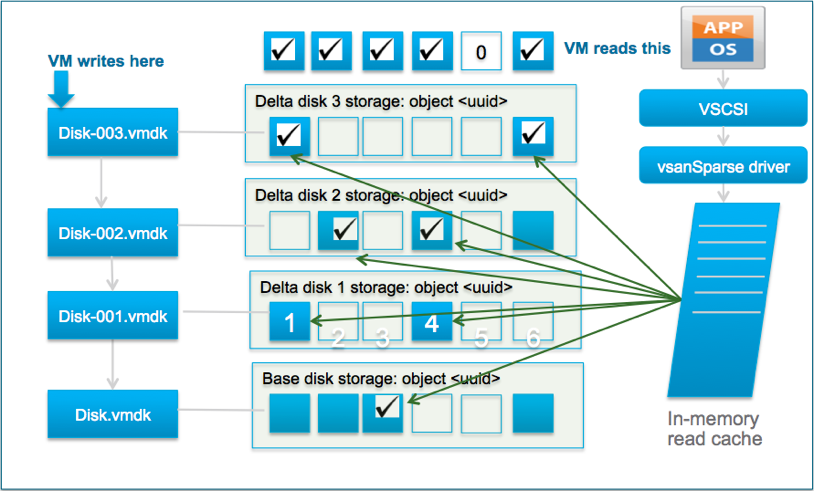
With vSAN 8 ESA the mechanism has changed and no longer does vSAN, or vSphere for that matter, create an additional object. vSAN ESA handles this on a meta-data level. In other words, instead of redirecting writes and traversing files for reads, vSAN now leverages a highly efficient B-Tree structure and pointers to keep track of which block is associated with which snapshot.

Not only is this more efficient from a capacity perspective, but more importantly it is very efficient from a performance standpoint. I ran half a dozen tests in my lab, and what I saw was a below 2% performance impact between a VM without a snapshot and a VM with one or multiple snapshots. I could NOT see a significant difference between the first or the fifth snapshot. I do want to point out that my lab is not officially certified to run vSAN ESA, nevertheless, I was very impressed with the results.

During the last run, I actually recorded the whole exercise. In this demo, I show the creation of one snapshot, while the VM is running a benchmark (HCIBench). Now, during the testing, I created not one but various snapshots and of course, I deleted all of them as well. You have all probably experienced extensive stun times during the deletion of a snapshot at times, and this is where vSAN ESA shines. The stun times have been reduced by 100 times, and that is something I am sure each of you will appreciate. Why have they been reduced drastically? Well, simply because we no longer have to copy data from one vSAN object to another. This makes a huge difference, not just for stun times, but also for performance in general (latency, IOPS, throughput). If you are interested, have a look at the demo!

Unexplored Territory #049 and #050, all about multi-cloud and cloud native workloads!

Duncan Epping · Jul 12, 2023 ·

I was working on my VMware Explore presentations so I forgot to post #049, figured I would post both at the same time for those who hadn’t seen these yet. In episode 049 we had two guests for the very first time, Gerrit Lehr and Andrea Siviero. Andrea and Gerrit talked us through the Multi-Cloud Adoption Framework and explained why customers are interested in this service and how it helps them meet their business goals. Listen to the full episode via Spotify (https://bit.ly/3Ny1EXE), Apple (https://bit.ly/449s2xA), or via the embedded player below.

Episode 050 focusses on Self-Managed Tanzu Mission Control, and we had Corey Dinkens as our guest. Corey discussed what Tanzu Mission Control is about, what the use case is, how customers are consuming it today, and why a self-managed solution makes sense for some customers compared to the SaaS offering. Interesting stuff if you ask me. Listen via Spotify (https://bit.ly/3XHU3dE), Apple (https://bit.ly/3XLm7g5), or use the embedded player below.

Seeing unexpected error messages during ISL failure with Stretched Cluster for secondary site

Duncan Epping · Jun 22, 2023 ·

I had a question this week from one of our field specialists, he ran into a situation where he saw lots of error messages about the fact that vSphere HA could not restart a certain workload during an ISL failure. Let me first explain the scenario, and also explain what vSAN does and doesn’t do. Let’s take the below situation.

Let’s assume Datacenter A is the “preferred site”, and Datacenter B is the “secondary site”. In case the ISL between Datacenter A and Datacenter B fails, the Witness (in a 3rd location) will bind itself automatically with Datacenter A. This means that VMs in Datacenter B will lose access to the vSAN Datastore.

From an HA perspective Datacenter A will have a primary (previously called master), and so will Datacenter B. The primary will detect that there are VMs that are not running, and it will try to restart these VMs. It will try to do this on both sides, and of course the site where access to the vSAN datastore is lost will see the restart fail.

Now here is the important aspect, of course depending on where/how vCenter Server is connected to these locations, it may, or may not, receive information about successful and unsuccessful restarts. I’ve seen situations where vCenter Server could only communicate with the primary in Datacenter B, and this would just lead to unsuccessful failover messages, while in reality all VMs were restarted in Datacenter A. The UI can give a hint by the way when you are in that situation, it will provide you the info on which host is the primary, and it will also tell you that there’s a “network isolation” or a “network partition”, and in this case of course that would be a “network partition”.

Performance Management Object reduced availability on stretched cluster

Duncan Epping · Jun 15, 2023 ·

I created a new lab environment not too long ago and I ran into this situation where the Performance Management Object showed up as Reduced Availability with no Rebuild in vSAN Skyline Health. This happened in my case because I created a Stretched Cluster configuration after I had already formed a cluster, which means that the performance management object was randomly placed across hosts without taking those “failure domains” into account. I completely forgot about it until someone on VMTN reminded me about this. I had two options, fix the existing perf database, or simply disable/enable the perf service to it is recreated.

As I had no data stored in the database I figured disable/enable is the easiest route. I looked for the option in vSphere 8.0 U1 but could not find it, it seems that the UI option no longer exists for whatever reason. How do I now disable/enable the service? Ruby vSphere Console (RVC) to the rescue!

When you log in to RVC you can simply run the following commands on the cluster object you want to disable/enable the performance service for. Fairly straight forward, and fixed the issue within a minute or so:

vsan.perf.stats_object_delete <cluster>
vsan.perf.stats_object_create <cluster>

I also documented this in the vSAN 8.0 ESA Deep Dive Book by the way, you can buy a paper copy or ebook on Amazon.

vSAN Stretched Cluster failure matrix

Duncan Epping · May 30, 2023 ·

The last couple of weeks I was involved internally in a discussion around the different vSAN stretched cluster failure scenarios. I wrote a lengthy email about how vSAN and HA would respond in certain scenarios. I have documented many of these over the years on my blog already, but never really published them as a whole.

In some of the scenarios below, I discuss a “partition”, a partition is a scenario where both the L3 connection to the witness is down and the inter site / inter switch link to the other site for one of the locations. So in the diagram above for instance, if I say that Site B is partitioned then it means that Site A can still communicate with the witness, but Site B cannot communicate with the Witness and cannot communicate with Site A either.

For all of the below scenarios the following applies, Site A is the preferred location and Site B is the secondary location. When it comes to the table, the first two columns refer to the policy setting for the VM as shown in the screenshot below. The third column refers to the location where the VM runs from a compute perspective. The fourth discusses the type of failure, and the fifth and sixth columns discuss the behavior witnessed.

Time to list the various scenarios, and no, it doesn’t include all failures that could occur but should discuss most scenarios which are important for a stretched cluster configuration. Do note, the below-discussed behavior will only be witnessed when the best practices, as documented here and here, are followed. Also note that the table has multiple pages, there are close to 30 scenarios described! If there are any questions feel free to leave a comment, if you feel a failure scenario is missing, also please leave a comment.

Site Disaster ToleranceFailures to TolerateVM LocationFailurevSAN behaviorHA behavior
None PreferredNo data redundancySite A or BHost failure Site AObjects are inaccessible if failed host contained one or more components of objectsVM cannot be restarted as object is inaccessible
None PreferredRAID-1/5/6Site A or BHost failure Site AObjects are accessible as there's site local resiliencyVM does not need to be restarted, unless VM was running on failed host
None PreferredNo data redundancy / RAID-1/5/6Site AFull failure Site AObjects are inaccessible as full site failedVM cannot be restarted in Site B, as all objects reside in Site A
None PreferredNo data redundancy / RAID-1/5/6Site BFull failure Site BObjects are accessible, as only Site A contains objectsVM can be restarted in Site A, as that is where all objects reside
None PreferredNo data redundancy / RAID-1/5/6Site APartition Site AObjects are accessible as all objects reside in Site AVM does not need to be restarted
None PreferredNo data redundancy / RAID-1/5/6Site BPartition Site BObjects are accessible in Site A, objects are not accessible in Site B as network is downVM is restarted in Site A, and killed by vSAN in Site B
None SecondaryNo data redundancy / RAID-1/5/6Site BPartition Site BObjects are accessible in Site BVM resides in Site B, does not need to be restarted
None PreferredNo data redundancy / RAID-1/5/6Site AWitness Host FailureNo impact, witness host is not used as data is not replicatedNo impact
None SecondaryNo data redundancy / RAID-1/5/6Site BWitness Host FailureNo impact, witness host is not used as data is not replicatedNo impact
Site MirroringNo data redundancySite A or BHost failure Site A or BComponents on failed hosts inaccessible, read and write IO across ISL as no redundancy locally, rebuild across ISLVM does not need to be restarted, unless VM was running on failed host
Site MirroringRAID-1/5/6Site A or BHost failure Site A or BComponents on failed hosts inaccessible, read IO locally due to RAID, rebuild locallyVM does not need to be restarted, unless VM was running on failed host
Site MirroringNo data redundancy / RAID-1/5/6Site AFull failure Site AObjects are inaccessible in Site A as full site failedVM restarted in Site B
Site MirroringNo data redundancy / RAID-1/5/6Site APartition Site AObjects are inaccessible in Site A as full site is partitioned and quorum is lostVM restarted in Site B
Site MirroringNo data redundancy / RAID-1/5/6Site AWitness Host FailureWitness object inaccessible, VM remains accessibleVM does not need to be restarted
Site MirroringNo data redundancy / RAID-1/5/6Site BFull failure Site AObjects are inaccessible in Site A as full site failedVM does not need to be restarted as it resides in Site B
Site MirroringNo data redundancy / RAID-1/5/6Site BPartition Site AObjects are inaccessible in Site A as full site is partitioned and quorum is lostVM does not need to be restarted as it resides in Site B
Site MirroringNo data redundancy / RAID-1/5/6Site BWitness Host FailureWitness object inaccessible, VM remains accessibleVM does not need to be restarted
Site MirroringNo data redundancy / RAID-1/5/6Site ANetwork failure between Site A and B (ISL down)Site A binds with witness, objects in Site B becomes inaccessibleVM does not need to be restarted
Site MirroringNo data redundancy / RAID-1/5/6Site BNetwork failure between Site A and B (ISL down)Site A binds with witness, objects in Site B becomes inaccessibleVM restarted in Site A
Site MirroringNo data redundancy / RAID-1/5/6Site A or Site BNetwork failure between Witness and Site A (or B)Witness object absent, VM remains accessibleVM does not need to be restarted
Site MirroringNo data redundancy / RAID-1/5/6Site AFull failure Site A, and simultaneous Witness Host FailureObjects are inaccessible in Site A and Site B due to quorum being lostVM cannot be restarted
Site MirroringNo data redundancy / RAID-1/5/6Site AFull failure Site A, followed by Witness Host Failure a few minutes laterPre vSAN 7.0 U3: Objects are inaccessible in Site A and Site B due to quorum being lostVM cannot be restarted
Site MirroringNo data redundancy / RAID-1/5/6Site AFull failure Site A, followed by Witness Host Failure a few minutes laterPost vSAN 7.0 U3: Objects are inaccessible in Site A, but accessible in Site B as votes have been recountedVM restarted in Site B
Site MirroringNo data redundancy / RAID-1/5/6Site BFull failure Site B, followed by Witness Host Failure a few minutes laterPost vSAN 7.0 U3: Objects are inaccessible in Site B, but accessible in Site A as votes have been recountedVM restarted in Site A
Site MirroringNo data redundancySite AFull failure Site A, and simultaneous host failure in Site BObjects are inaccessible in Site A, if components reside on failed host then object is inaccessible in Site BVM cannot be restarted
Site MirroringNo data redundancySite AFull failure Site A, and simultaneous host failure in Site BObjects are inaccessible in Site A, if components do not reside on failed host then object is accessible in Site BVM restarted in Site B
Site MirroringRAID-1/5/6Site AFull failure Site A, and simultaneous host failure in Site BObjects are inaccessible in Site A, accessible in Site B as there's site local resiliencyVM restarted in Site B
  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 3
  • Page 4
  • Page 5
  • Page 6
  • Page 7
  • Interim pages omitted …
  • Page 336
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in