• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

How to disable Datastore Heartbeating

Duncan Epping · Feb 25, 2013 ·

I have had this question multiple times now, how do I disable datastore heartbeating? Personally, I don’t know why you would ever want to do this… but as multiple people have asked I figured I would write it down. There is no “disable” button unfortunately, but there is a work-around. Below are the steps you need to take to disable datastore heartbeating.

vSphere Client:

  • Right Cluster object
  • Click “Edit Settings”
  • Click “Datastore Heartbeating”
  • Click “Select only from my preferred datastores”
  • Do not select any datastores

Web Client:

  • Click “Cluster object”
  • Click “Manage” tab
  • Click “vSphere HA”
  • Click “Edit button” on the right side
  • Click “Datastore Heartbeating”
  • Click “Select only from my preferred datastores”
  • Do not select any datastores

It is as simple as that… However, let me stress that this is not something that I would recommend doing. Only when you are troubleshooting and need it disabled for whatever reason, please make sure to enable it when you are done.

VMware View Infrastructure Resiliency whitepaper published

Duncan Epping · Feb 24, 2013 ·

One of the white papers I worked on in 2012 when I was part of Technical Marketing was just published. This white paper is about VMware View infrastructure resiliency. It is a common question from customers, and now with this white paper you can explore the different options and understand the impact of these options. Below is a link to the paper and the description is has on the VMware website.

VMware View Infrastructure Resiliency: VMware View 5 and VMware vCenter Site Recovery Manager
“This case study provides insight and information on how to increase availability and recoverability of a VMware View infrastructure using VMware vCenter Site Recovery Manager (SRM), common disaster recovery (DR) tools and methodologies, and vSphere High Availability.”

I want to thank Simon Richardson, Kris Boyd, Matt Coppinger and John Dodge for working with me on this paper. Glad it is finally available!

Introducing startup PernixData – Out of stealth!

Duncan Epping · Feb 20, 2013 ·

There are many startups out there that do something with storage these days. To be honest, many of them do the same thing and at times I wonder why on earth everyone focuses on the same segment and tries to attack it with the same product / feature set. One of the golden rules for any startup should be that you have a unique solution that will sell itself. Yes I realize that it is difficult, but if you want to succeed you will need to stand out.

About a year ago Satyam Vaghani (former VMware principal engineer who was responsible for VMFS, VAAI, VVOLs etc.) and Poojan Kumar (former VMware Data products lead and ex-Oracle Exadata founder) decided to start a company – PernixData. PernixData was conceptualized based on their experiences working on the intersection of virtualization, flash based storage and data. Today PernixData is revealed to the world. For those who don’t know, Pernix means “agile”. But what is PernixData about?

How many of you haven’t experienced storage performance problems? It probably is, in fact, the number one bottleneck in most virtualized environments. Convincing your manager (director / VP) that you need a new ultra-fast (and expensive) storage device is not easy; far from it. On top of that, data will always hit the network first before being acknowledged and every read will go over your storage network. How cool would it be if there was a seamless software solution that solves all your storage performance problems without you requiring to rip and replace your existing storage assets?

Server-side flash overcomes problems associated with network based storage and server-side caching solutions provide some respite. Yet, server-side caching solutions usually neither satisfy enterprise class requirements for availability nor transparently support clustered hypervisor features such as VMware vMotion. In addition, while they accelerate reads they fail to do much for writes. Customers are then stuck between either overhauling their entire storage infrastructure or going with caching solutions that work for limited use cases. PernixData is about to release a cool new product – a flash virtualization platform – that bridges this gap. By picking up where hypervisors left off, PernixData is planning to become the VMware of server flash and is aiming to do to server flash what VMware did to CPU and memory. So, what is this flash virtualization platform and why would you need it?

PernixData’s flash virtualization platform virtualizes all flash resources across all server nodes in a vCenter Server cluster into a single high-performance, enterprise class data tier. The great thing is that this happens in a transparent way. PernixData sits completely within the hypervisor and in the data-path of your virtual machine. Note that there are no requirements to install anything in the guest (virtual machine). PernixData is not a virtual appliance because virtual appliances introduce performance overhead and would need to be managed with all costs and complexity associated.

PernixData is also flash technology agnostic. It can leverage SSD or PCIe flash (or both) within the platform. The nice thing is that PernixData uses a scale-out architecture. As you add hosts with flash they can be dynamically added to the platform. On top of that, PernixData does both read and write acceleration while providing full data protection and is fully compatible with VM mobility solutions like vMotion, Storage vMotion, HA, DRS and Storage DRS.

Even more exciting PernixData will support both Write-through and Write-back modes. The cool part is that PernixData also ensures IO is replicated for high availability purposes. You don’t want to run your VM in Write-back mode when you cannot guaranteed data is highly available right?! I guess that is one of the unique selling points of the solution. A distributed, scale out, flash virtualization platform which is not only flash agnostic but also non-disruptive for your virtual workloads.

I would imagine this is many times cheaper than buying a new storage array. Even without knowing what the cost of PernixData will be, or which flash device (PCIe or SSD) you would decide to use… I bet when it comes to overall costs of the solution (product + implementation costs) it will be many many times cheaper.

As I started off with, the golden rule for any startup should be that they have a unique solution that sells itself. I am confident that PernixData FVP has just that by being a disruptive technology that solves a big problem in virtualized environments  in a scale-out and transparent manner while leveraging your existing storage investments.

If you want to be kept up to date, make sure to follow Satyam, Poojan , Charlie and PernixData on twitter. If you are interested in joining the PernixData FVP Beta, make sure to sign up!

Make sure to also read Frank’s article on PernixData.

<update>

I recommend watching the Storage Field Day videos for more details from Satyam Vaghani himself, note the playlist this is 4 videos!

</update>

Vote for the top virtualization Blogs / 2012 looking back!

Duncan Epping · Feb 20, 2013 ·

Yes, it is that time of the year again… vSphere-land.com’s voting for the top virtualization blogs has started again. Of course I am hoping to end up somewhere at the top of the list again, but I realize like no one else that this is not a given. The competition once again is huge, there are a couple of new-comers which has published some outstanding work. Personally I am a huge fan of Cormac Hogan’s work and I hope he will make it in to the top 10 this year, I sure as hell voted for him! Of course I expect my friends like Frank Denneman, Alan Renouf, Massimo Referre and William Lam to also hit the top 10.

I am hoping each of you will select the top-10 blogs again based on quality, relevancy, longevity and frequency. (I personally find length of the article irrelevant, content is King!) I always use the yearly voting to look back at what happened the last 12 months. What happened in 2012, what has kept me busy?

For me 2012 started with Partner Exchange. Presented a 2-hr workshop on how to design a Cloud Infrastructure, together with Dave Hill (he is on the list as well, so vote for him :-)) and guests Frank Denneman and Chris Colotti. On top of that Chris Colotti and I presented a DR solution for vCloud Director based environments. This is something that people had been waiting on for a long time. I came up with the process/concept for this and also published a whitepaper on this topic. The same concept can be used for VMware View environments by the way, white paper out soon! I published a whole bunch of other white papers (1, 2) this year as part of my Tech Marketing responsibilities, of which the vMSC Best Practices paper is probably the most read and best received. I managed to get a couple of sessions approved at VMworld and had a blast presenting with my buddy Lee Dilworth. Also being a VMworld “Expert” was once again an awesome experience, I especially enjoyed the group discussions. I also presented as a couple of VMUGs (belgium, ireland, uk) and last but not least, published the vSphere 5.1 Clustering Deepdive… which happened to be the most sold book at VMworld San Francisco.

Along the way I managed to crank out an article or two hundred, and my blog went down during the vSphere 5.1 launch due to the massive amount of traffic. I can tell you that my hosting company was surprised as they thought it was a DDOS attack, but then they figured out it was just a massive amount of people hitting my site on the same day. I guess thanks for that 🙂

I did want to list my 10 top articles over the last 12 months in no particular order:

  • Back To Basics: Install, Configure and use vSphere Replication
  • VXLAN Essentials (3 posts): configuring, requirements and usecases
  • The number of vSphere HA heartbeat datastores for this host is 1 which is less than required 2 (this is one that proofs that you don’t always need to write lengthy deepdive articles)
  • vSphere HA fail-over in action – aka reading the log files
  • Thinking about a Stretched vCloud Director Deployment
  • IOps
  • vSphere Metro Storage Cluster – Uniform vs Non-Uniform
  • The vSphere 5.1 HA Deepdive Page

Thanks again to Eric Siebert who spends a MASSIVE amount of time going through the voting, filtering out discrepancies and making sure it all is done in a fair manner! Make sure to bookmark his website, add it to your RSS reader and follow him on twitter. So what are you waiting for, head on over and take the survey!

vSphere HA 5.x restart attempt timing

Duncan Epping · Feb 18, 2013 ·

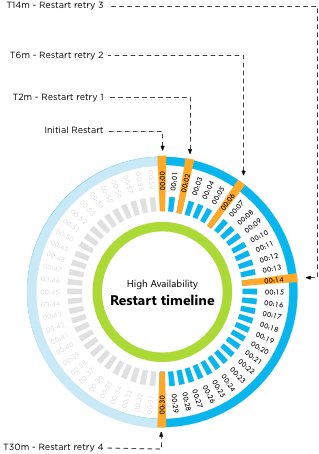
I wrote about how vSphere HA 5.x restart attempt timing works a long time ago but there appears still to be some confusion about this. I figured I would clarify this a bit more, I don’t think I can make it more simple than this:

  • Initial restart attempt
  • If the initial attempt failed, a restart will be retried after 2 minutes of the previous attempt
  • If the previous attempt failed, a restart will be retried after 4 minutes of the previous attempt
  • If the previous attempt failed, a restart will be retried after 8 minutes of the previous attempt
  • If the previous attempt failed, a restart will be retried after 16 minutes of the previous attempt

After the fifth failed attempt the cycle ends. Well that is, unless a new master host is selected (for whatever reason) between the first and the fifth attempt. In that case, we start counting again. Meaning that if a new master is selected after attempt 3, the new master will start with the “initial restart attempt.

Or as Frank Denneman would say:

vSphere HA 5.x restart attempt timing


** Disclaimer: This article contains references to the words master and/or slave. I recognize these as exclusionary words. The words are used in this article for consistency because it’s currently the words that appear in the software, in the UI, and in the log files. When the software is updated to remove the words, this article will be updated to be in alignment. **

  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 200
  • Page 201
  • Page 202
  • Page 203
  • Page 204
  • Interim pages omitted …
  • Page 502
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in