• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

VSAN Healthcheck Plugin requires DRS??

Duncan Epping · Dec 11, 2015 ·

I had a question today on my blog from a user who said that the VSAN Healthcheck Plugin was great but unfortunately required DRS to be able to install/configure it, which means that if you have vSphere Standard you can’t use. A very valid point, at least for the first version of the healthcheck plugin. However that problem has been fixed for a while now. I haven’t seen anyone pointing it out so I figured I would write a couple of lines about it for those who want to use it as I figure that more have hit this problem with the first release of the healthcheck plugin and haven’t seen that it has been fixed yet.

As of VSAN Healthcheck Plugin version 6.0.1 it is no longer required to have DRS enabled (this was a bug). You can find the link to download version 6.0.1 below:

  • Download 6.0.1 – https://my.vmware.com/web/vmware/details?downloadGroup=VSANHEALTH600&productId=492
  • Release notes 6.0.1 – https://www.vmware.com/support/vsphere6/doc/vmware-virtual-san-healthcheck-601-release-notes.html

For those who aren’t using the Healthcheck yet and are running vSphere 6.0, it is highly recommended! With the newer versions of vSphere 6.0 it will always come included (U1 and up). It has some great health checks that will enable you to validate the state of your VSAN cluster in a simple overview. I personally find the pro-active tests very valuable, especially the “burn in/perf” type tests, and of course the multi-cast test.
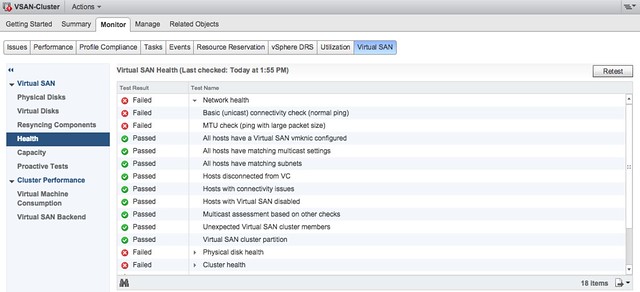
VSAN Healthcheck Plugin

And there is more coming pretty soon, been testing the next version of this in my lab and I must say that it looks great. Having all of the perf stats straight in the Web Client is definitely making life easier. Hopefully it is out soon!

data copy management / converged data management / secondary storage

Duncan Epping · Dec 3, 2015 ·

At the Italian VMUG I was part of the “Expert panel” at the end of the event. One of the questions was around innovation in the world of IT, what should be next. I knew immediately what I was going to answer: backup/recovery >> data copy management. My key reason for it being is that we haven’t seen much innovation in this space.

And yes before some of my community friends will go nuts and point at Veeam and some of the great stuff they have introduced over the last 10 years, I am talking more broadly here. Many of my customers are still using the same backup solution they used 10-15 years ago, yes it is a different version probably, but all the same concepts apply. Well maybe tapes have been replaced by virtual tape libraries stored on a disk system somewhere, but that is about it. The world of backup/recovery hasn’t evolved really.

Over the last years though we’ve been seeing a shift in the industry. This shift started with companies like Veeam and then continued with companies like Actifio, and this is now accelerated by companies like Cohesity and Rubrik. What is different from what these guys offer versus the more traditional backup solution… well the difference is that all of these are more than backup solutions, they don’t focus on a single use case. They “simply” took a step back and looked at what kind of solutions are using your data today, who is using it, how and of course what for. On top of that, where the data is stored is also a critical part of it of the puzzle.

In my mind Rubrik and Cohesity are leading the pack when it comes to this new wave of, they’ve developed a solution which is a convergence of different products (Backup / Scale-out storage / Analytics / etc). I used “convergence” on purpose, as this is what it is to me “converged data (copy) management”. Although not all use cases may have reached the full potential yet, the vision is pretty clear, and multiple layers have already converged, even if we would just consider backup and scale-out storage. I said pretty clear as the various startups have taken different messaging approaches. This is something that became obvious during the last Storage Field Day where Cohesity presented. Different story than for instance Rubrik had during Virtualization Field Day. Just as an example, Rubrik typical;y leads with data protection and management, where Cohesity’s messaging appears to be more around being a “secondary storage platform”. This in the case of Cohesity lead to discussions (during SFD) around what secondary storage is, how you get data on the platform and finally then what you can do with it.

To me, and the folks at these startups may have completely different ideas around this, there are a couple of use cases which stand out for a converged data management platform, use cases which I would expect to be the first target and I will explain why in a second.

  1. Backup and Recovery (long retention capabilities)
  2. Disaster Recovery using point in time snapshots/replication (relatively short retention capabilities and low RPO)

Why are these the two use cases to go after first? Well it is the easiest way to suck data in to your system and make your system sticky. It is also the market where innovation is needed, on top of that you need to have the data in your system first before you can do anything with it. Before some of the other use cases start to make sense like “data analytics”, or creating clones for “test / dev” purposes, or spinning up DR instances whether that is in your remote site or somewhere in the cloud.

The first use case (backup and recovery) is something which all of them are targeting, the second one not so much at this point. In my opinion a shame, as it could definitely be very compelling for customers to have these two data availability concepts combined. Especially when some form of integration with an orchestration layer can be included (think Site Recovery Manager here) and protection of workloads is enabled through policy. Policy in this case allowing you to specify SLA for data recovery in the form of recovery point, recovery time and retention. And then when needed, you as a customer have the choice of how you want to make your data available again: VM fail-over, VM recovery, live/instant recovery, file granular or application/database object level recovery and so on and so forth. Not just that, from that point on you should be capable of using your data for other use cases, the use cases I mentioned earlier like analytics, test/dev copies etc.

We aren’t there yet, better said we are far from there, but I do feel this is where we are headed towards… and some are closing in faster than others. I can’t wait for all of this to materialize and we start making those next steps and see what kind of new use cases can be made possible on converged data management platforms.

VSAN enabling Sky to be fast / responsive / agile…

Duncan Epping · Nov 30, 2015 ·

Over the last couple of months I’ve been talking to a lot of VSAN customers. A while ago I had a very interesting use case with a deployment on an Oil Platform. This time it is a more traditional deployment: I had the pleasure of talking to James Cruickshank who works for Sky. Sky is Europe’s leading entertainment company, serving 21 million customers across five countries: Italy, Germany, Austria, the UK and Ireland.
James is part of Sky’s virtualisation group which primarily focusses on new technologies. In short, the team figures out if a technology will benefit Sky, how it works, how to implement it and how to support it. He documents all of his findings then develops and delivers the solution to the operations team.

One of the new products that James is working with is Virtual SAN. The project started in March and Sky has a handful of VSAN ready clusters in each of its strategic data centres. These clusters currently have ESXi 5.5 hosts with one 400GB SSD and 4 x 4TB NL-SAS drives all connected over 10GbE, a significant amount of capacity per host. The main reason for that is that there is a requirement for Sky to run with FTT=2 (for those who don’t know, this means that a 1TB disk will consume ~3TB). James anticipates VSAN 6 will be deployed with a view to deliver production workloads in Q1 2016.

We started talking about the workloads Sky had running and what some of the challenges were for James. I figured that, considering the size of the organisation and the number of workloads it has, getting all the details must not have been easy. James confirmed that it was difficult to get an understanding of the IO profile and that he spent a lot of time developing representative workloads. James mentioned that when he started his trial the VSAN Assessment Tool wasn’t available yet, and that it would have saved him a lot of time.

So what is Sky running? For now mainly test/dev workloads. These clusters are used by developers for short term usage, to test what they are building and trash the environment, all of which is enabled through vRealize Automation. Request a VM or multiple, deploy on VSAN cluster and done. So far in Sky’s deployment all key stakeholders are pleased with the technology as it is fast and responsive, and for the ops team in particular it is very easy to manage.

James mentioned that recently he has been testing both VSAN 5.5 and 6.0. He was so surprised about the performance increase that he re-ran his test multiple times, then had his colleagues do the same, while others reviewed the maths and the testing methodology. Each time they came to the same conclusion; there was an increase in excess of 60% performance between 5.5 and 6.0 (using a “real-world” IO profile), an amazing result.

Last question for me was around some of the challenges James faced. The first thing he said was that he felt the technology was fantastic. There were new considerations around the design/sizing of their VSAN hosts, the increased dependency on TCP/IP networks and the additional responsibilities for storage placed within the virtualisation operations team. There were also some minor technical challenges, but these were primarily from an operational perspective, and with vSphere / VSAN 5.5. In some cases he had to use RVC, which is a great tool, but as it is CLI based it does have a steep learning curve. The HealthCheck plugin has definitely helped a lot with 6.0 to improve this.

Another thing James wanted to call out is that in the current VSAN host design Sky uses an SSD to boot ESXi, as VSAN hosts with more than 512GB RAM cannot boot from SD card. This means the company is sacrificing a disk slot which could have been used for capacity, when it would prefer to use SD for boot if possible to optimise hardware config.

I guess it is safe to say that Sky is pleased with VSAN and in future the company is planning on adopting a “VSAN first” policy for a proportion of their virtual estate. I want to thank Sky, and James in particular, for taking the time to talk to me about his experience with VSAN. It is great to get direct feedback and hear the positive stories from such a large company, and such an experienced engineer.


Doing a stretched VSAN design?

Duncan Epping · Nov 27, 2015 ·

As I have given various people already individually the formulas needed to calculate how much bandwidth is required I figured I would share this as well. If you are doing a stretched VSAN design you will want to read this excellent paper by Jase McCarty. This paper describes the bandwidth requirements between the “data sites” and from the data sites to the “witness site”. It provides the formula needed, and it will show you that the “general guidelines” provided during launch were relatively conservative. In many cases especially the the connection to the witness location can be low bandwidth. Just have a read when you are designing a stretched VSAN and do the math.

http://www.vmware.com/files/pdf/products/vsan/vmware-virtual-san-6.1-stretched-cluster-bandwidth-sizing.pdf

Virtual SAN: Generic storage platform of the future

Duncan Epping · Nov 20, 2015 ·

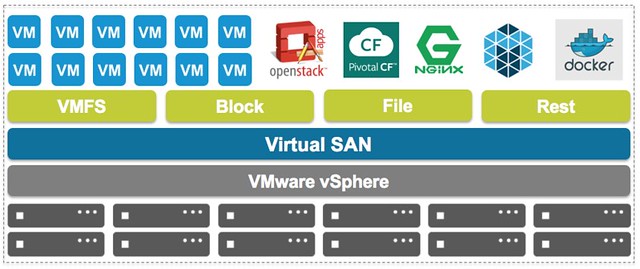
Over the last couple of weeks I have been presenting at various events on the topic of Virtual SAN. One of the sections in my deck is a bit about the future of Virtual SAN and where it is heading towards. Someone tweeted one of the diagrams in my slides recently which got picked up by Christian Mohn who provided his thoughts on the diagram and what it may mean for the future. I figured I would share my story behind this slide, which is actually a new version of a slide that was originally presented by Christos and also discussed in one of his blog posts. First, lets start with the diagram:

If you look at VSAN today and ask people what VSAN is today then most will answer: a “virtual machine” storage system. But VSAN to me is much more than that. VSAN is a generic object storage platform, which today is used to primarily store virtual machines. But these objects can be anything if you ask me, and on top of that can be presented as anything.

So what is it VMware is working towards, what is our vision? VSAN was designed to serve as a generic object storage platform from the start, and is being extended to serve as a platform to different types of data by providing an abstraction layer. In the diagram you see “REST” and “FILE” and things like Mesos and Docker, it isn’t difficult to imagine what types of workloads we envision to run on top of VSAN and what types of access you have to resources managed by VSAN. This could be through a native Rest API that is part of the platform which can be used by developers directly to store their objects on or through the use of a specific driver for direct “block” access for instance.

Combine that with the prototype of the distributed filesystem which was demonstrated at VMworld and I think it is fair to say that the possibilities are endless. VSAN isn’t just a storage system for virtual machines, it is a generic object based storage platform which leverages local resources and will be able to share those in a clustered fashion in any shape or form in the future. Christian definitely had a point, in which shape or form all of this will be delivered has to be seen though, this is not something I can (or want) to speculate on. Whether that is through Photon Platform, or something else is in my opinion besides the point. Even today VSAN has no dependencies on vCenter Server and can be fully configured, managed and monitoring using the APIs and/or the different command-line interface options we offer. Agility and choice have always been the key design principles for the platform.

Where things will go exactly and when this will happen is still to be seen. But if you ask me, exciting times are ahead for sure, and I can’t wait to see how everything plays out.


  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 119
  • Page 120
  • Page 121
  • Page 122
  • Page 123
  • Interim pages omitted …
  • Page 502
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in