• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

BC-DR

Can I still provision VMs when a vSAN Stretched Cluster site has failed? Part II

Duncan Epping · Dec 18, 2019 ·

3 years ago I wrote the following post: Can I still provision VMs when a VSAN Stretched Cluster site has failed? Last week I received a question on this subject, and although officially I am not supposed to work on vSAN in the upcoming three months I figured I could test this in the evening easily within 30 minutes. The question was simple, in my blog I described the failure of the Witness Host, what if a single host fails in one of the two “data” fault domains? What if I want to create a snapshot for instance, will this still work?

So here’s what I tested:

  • vSAN Stretched Cluster
  • 4+4+1 configuration
    • Meaning, 4 hosts in each “data site” and a witness host, for a total of 8 hosts in my vSAN cluster
  • Create a VM with cross-site protection and RAID-5 within the location

So I first failed a host in one of the two data sites. When I fail the host, the following is what happens when I create a VM with RAID-1 across sites and RAID-5 within a site:

  • Without “Force Provisioning” enabled the creation of the VM fails
  • When “Force Provisioning” is enabled the creation of the VM succeeds, the VM is created with a RAID-0 within 1 location

Okay, so this sounds similar to the originally described scenario, in my 2016 blog post, where I failed the witness. vSAN will create a RAID-0 configuration for the VM. When the host returns for duty the RAID-1 across locations and RAID-5 within each location is then automatically created. On top of that, you can snapshot VMs in this scenario, the snapshots will also be created as RAID-0. One thing to mind is that I would recommend removing “force provisioning” from the policy after the failure has been resolved! Below is a screenshot of the component layout of the scenario by the way.

I also retried the witness host down scenario, and in that case, you do not need to use the “force provisioning” option. One more thing to note. The above will only happen when you create a RAID configuration which is impossible to create as a result of the failure. If 1 host fails in a 4+4+1 stretched cluster you would like to create a RAID-1 across sites and a RAID-1 within sites then the VM would be created with the requested RAID configuration, which is demonstrated in the screenshot below.

VMworld Reveals: Disaster Recovery / Business Continuity enhancements! (#HCI2894BU and #HBI3109BU)

Duncan Epping · Sep 4, 2019 ·

At VMworld, various cool new technologies were previewed. In this series of articles, I will write about some of those previewed technologies. Unfortunately, I can’t cover them all as there are simply too many. This article is about enhancements in the business continuity/disaster recovery space. There were 2 sessions where futures were discussed, namely HCI2894BU and HBI3109BU. Please note that this is a brief summary of those sessions, and these are discussing a Technical Preview, these features/products may never be released, and these previews do not represent a commitment of any kind, and this feature (or it’s functionality) is subject to change. Now let’s dive into it, what can you expect for disaster recovery in the future?

The first session I watched was HCI2894BU, this was all about Site Recovery Manager. I think the most interesting part is the future support for Virtual Volumes (vVols) for Site Recovery Manager. It may sound like something simple, but it isn’t. When the version of SRM ships that supports vVols keep in mind that your vVol capable storage system also needs to support it. At day 1 HPe Nimble, HPe 3PAR and Pure Storage will support it and Dell EMC and NetApp are actively working on support. The requirements are that the storage system needs to be vVols 2.0 compliant and support VASA 3.0. Before they dove into the vVols implementation, some history was shared and the current implementation. I found it interesting to know that SRM has over 25.000 customers and has protected more than 3.000.000 workloads over the last decade.

[Read more…] about VMworld Reveals: Disaster Recovery / Business Continuity enhancements! (#HCI2894BU and #HBI3109BU)

vSphere HA virtual machine failed to failover error on VMs in a partitioned cluster

Duncan Epping · Apr 12, 2019 ·

I received two questions this week around partition scenarios where after the failure has been lifted some VMs display the error message “vSphere HA virtual machine failed to failover”. The question that then arises is: why did HA try to restart it, and why did it fail? Well, first of all, this is an error that in most cases you can safely ignore. There’s a KB on the topic which gives a bit of detail to be found here, but let me explain also in a bit more depth.

In a partitioning scenario, each partition will have its own primary node. If there is no form of communication (datastore/network) possible, what the HA primary will do is it will list all the VMs that are currently not running within that partition. It will also want to try to restart those VMs. A partition is extremely uncommon in normal environments but may happen in a stretched cluster. In a stretched cluster when a partition happens a datastore only belongs to 1 location. The VMs which appear to be missing typically are running in the other location, as typically the other location will have access to that particular datastore. Although the primary has listed these VMs as “missing and need to restart” it will not be able to do this. Why? It doesn’t have access to the datastore itself, or when it has access to the datastore the files are locked as the VMs are still running. As a result, this will, unfortunately, be reported as a failed failover. Even though the VM was still running and there was no need for a failover. So if you hit this during certain failure scenarios, and the VMs were running as you expected, you can safely ignore this error.

How to test failure scenarios!

Duncan Epping · Mar 14, 2019 ·

Almost on a weekly basis, I get a question about unexpected results during the testing of certain failure scenarios. I usually ask first if there’s a diagram that shows the current configuration. The answer is usually no. Then I would ask if they have a failure testing matrix that describes the failures they are introducing, the expected result and the actual result. As you can guess, the answer is usually “euuh a what”? This is where the problem usually begins. The problem usually gets worse when customers try to mimic a certain failure scenario.

What would I do if I had to run through failure scenarios? When I was a consultant we always started with the following:

  • Document the environment, including all settings and the “why”
  • Create architectural diagrams
  • Discuss which types of scenarios would need to be tested
  • Create a failure testing matrix that includes the following:
    • Type of failure
    • How to create the scenario
      • Preferably include diagrams per scenario displaying where the failure is introduced
    • Expected outcome
    • Observed outcome

What I would normally also do is describe in the expected outcome section the theory around what should happen. Maybe I should just give an example of a failure and how I would describe it more or less.

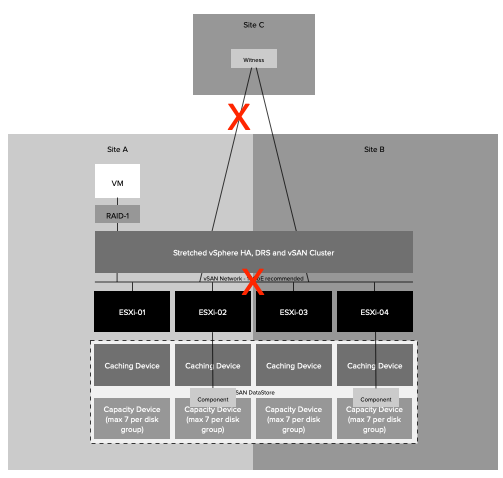
Type Failure: Site Partition

How to: Disable links between Site-A / Site-C and Site-A / Site-B

Expected outcome: The secondary location will bind itself with the witness and will gain ownership over all components. In the preferred location, the quorum is lost, as such all VMs will appear as inaccessible. vSAN will terminate all VMs in the preferred location. This is from an HA perspective however a partition and not an isolation as all hosts in Site-A can still communicate with each other. In the secondary location vSphere HA will notice hosts are missing. It will validate that the VMs that were running are running, or not running. All VMs which are not running, and have accessible components, will be restarted in the secondary location.

Observed outcome: The observed outcome was similar to the expected outcome. It took 1 minute and 30 seconds before all 20 test VMs were restarted.

In the above example, I took a very basic approach and didn’t even go into the level of depth you probably should go. I would, for instance, include the network infrastructure as well and specify exactly where the failure occurs, as this will definitely help during troubleshooting when you need to explain why you are observing a particular unexpected behavior. In many cases what happens is that for instance a site partition is simulated by disabling NICs on a host, or by closing certain firewall ports, or by disabling a VLAN. But can you really compare that to a situation where the fiber between two locations is damaged by excavations? No, you can not compare those two scenarios. Unfortunately this happens very frequently, people (incorrectly) mimic certain failures and end up in a situation where the outcome is different than expected. Usually as a result of the fact that the failure being introduced is also different than the failure that was described. If that is the case, should you still expect the same outcome? You probably should not.

Yes I know, no one likes to write documentation and it is much more fun to test things and see what happens. But without recording the above, a successful implementation is almost impossible to guarantee. What I can guarantee though is that when something fails in production, you most likely will not see the expected behavior when you have not tested the various failure scenarios. So please take the time to document and test, it is probably the most important step of the whole process.

HA Admission Control Policy: Dedicated Failover Hosts

Duncan Epping · Feb 5, 2019 ·

This week I received some questions on the topic of HA Admission Control. There was a customer that had a cluster configured with the dedicated failover host admission control policy and they had no clue why. This cluster had been around for a while and it was configured by a different admin, who had left the company. As they upgraded the environment they noticed that it was configured with an admission control policy they never used anywhere else, but why? Well, of course, the design was documented, but no one documented the design decision so that didn’t really help. So they came to me and asked what it exactly did and why you would use it.

Let’s start with that last question, why would you use it? Well normally you would not, you should not. Forget about it, well unless you have a specific use case and I will discuss that later. What does it do?

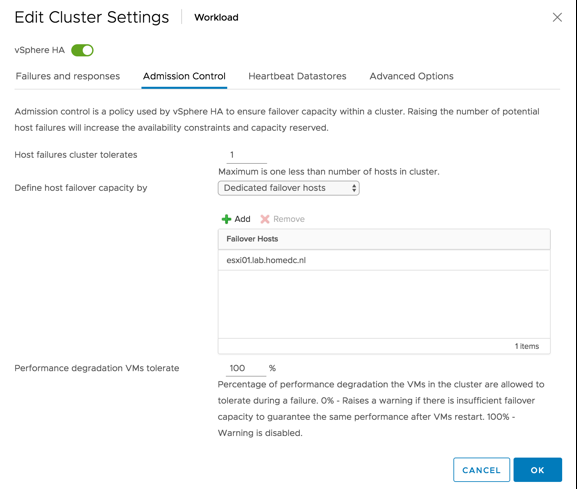
When you designate hosts as failover hosts, they will not participate in DRS and you will not be able to run VMs on these hosts! Not even in a two-host cluster when placing one of the two in maintenance. These hosts are literally reserved for failover situations. HA will attempt to use these hosts first to failover the VMs. If, for whatever reason, this is unsuccessful, it will attempt a failover on any of the other hosts in the cluster. For example, in a when two hosts would fail, including the hosts designated as failover hosts, HA will still try to restart the impacted VMs on the host that is left. Although this host was not a designated failover host, HA will use it to limit downtime.

As can be seen above, you select the correct admission control policy and then add the hosts. As mentioned earlier, the hosts added to this list will not be considered by DRS at all. This means that the resources go wasted unless there’s a failure. So why would you use it?

  • If you need to know where a VM runs all the time, this admission control policy dictates where the restart happens.
  • There is no resource fragmentation, as a full host (or multiple) worth of resources will be available to restart VMs on, instead of 1 host worth of resources across multiple hosts.

In some cases, the above may be very useful, for instance knowing where a VM is all the time could be required for regulatory compliance, or could be needed for licensing reasons when you run Oracle for instance.

  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 6
  • Page 7
  • Page 8
  • Page 9
  • Page 10
  • Interim pages omitted …
  • Page 64
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in