• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

BC-DR

Announcing VMware Cloud Disaster Recovery! (VCDR)

Duncan Epping · Sep 30, 2020 ·

Most of you probably saw the announcements around the acquisition of Datrium not too long ago. One of the major drivers for that acquisition was the Disaster Recovery solution which Datrium developed. This week at VMworld this service was announced as a new VMware disaster recovery option. The service is named VMware Cloud Disaster Recovery, and it provides the ability to replicate workloads from on-prem into cloud storage, and recover from cloud storage into VMware Cloud on AWS! The three key pillars of the service are ease of use, fast recovery, cloud economics.

The solution is extensively covered in three VMworld sessions (HCI2876, HCI2886, HCI2865). I have watched all three and will provide a short summary here. What capabilities does VMware Cloud DR (VCDR) provide and why is VMware heading into this space?

The why was well explained by Mark Chuang in HCI2876, customers are saying that:

  • “DR is very complex and expensive to manage, and I can’t add IT Headcount”
  • “Our data grows 10-15% every year, with physical DR it is hard to accommodate the growth in the datacenter to meet the needs”
  • “We only test full DR once a year because it is disruptive. Any time there is a major change, how can we know it still works? It is a huge issue!”

I guess that makes it clear why VMware is interested in this space, it is a huge problem for customers and the solution typically comes at a high cost. VMware has always been in the business of solving complex solutions in preferably a simple way, and that is exactly what VMware Cloud Disaster Recovery delivers, a simple solution at a relatively low cost.

So what does it bring from a feature/functionality stance?
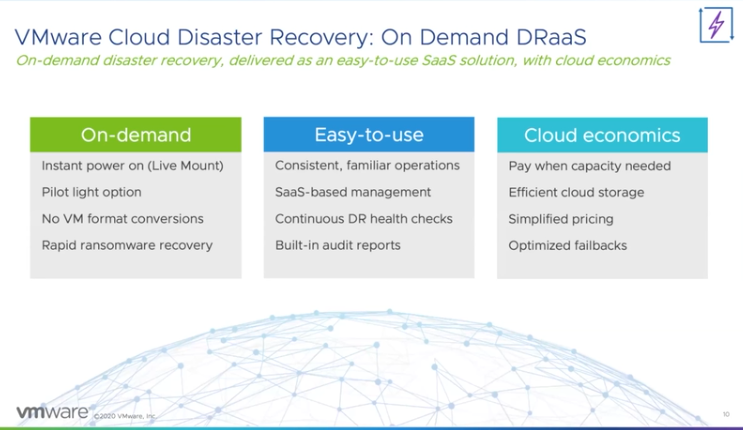
it all starts with cloud economics, to which ease-of-use also contributes, in my opinion. VMware Cloud Disaster Recovery is super simple to configure and it replicates data to “cheap and deep” cloud storage. This ensures that the cost can be kept low, and note that all of the typical cost that comes with cloud storage (network etc) are all included in the service offering by VMware. The challenge however typically with cloud storage is that it is relatively slow when it comes to restoring, but this is where the “on-demand” capabilities come into play. VMware Cloud DR provides the ability to instantly power-on workloads through a live mount option, without the need to convert the stored data back to a VM format.

When configuring the VMware Cloud DR solutions you will need to install/configure a DRaaS Connector on-prem. This on-prem Connector connects you to the SaaS platform and will provide the required details to the SaaS Orchestrator, note that you can have multiple DRaaS connectors for resiliency and performance reasons. When the connection is configured you will then be able to create “Protection Groups” and “DR Plans”. Those who have worked with Site Recovery Manager will recognize the terms. For those who haven’t:

  • Protection Groups – These groups list the workloads which will be protected by VMware Cloud DR. Of course you can define the protection schedule, basically how many snapshots need to be shipped remote cloud storage per day/week/month.
  • DR Plans – These plans list workloads that would need to be failed over when the plan is triggered, and for instance, include the order in which the workloads need to be powered on. Also, if workloads need to get a different IP address in the cloud, then you can specify this here also.

Of course besides creating protection groups and DR plans you have the ability to test and failover the workloads in those plans, again, very similar to what Site Recovery Manager offers. Before I forget, you will have the option of course to select the snapshot you want to recover from. So you can go back to any point in time. What is unique here is that VMs are powered without (initially) moving data from cloud storage to your VMware Cloud on AWS. It basically mounts an NFS share from the SaaS platform and the scale-out file system ensures that the VMs can be instantly be powered on. After you have tested the recovery you can then decide to migrate the VMs to your SDDC, or you can of course also discard the workloads if that is something you desire. Last but not least, of course, you also have the ability to replicate back to on-prem, so that you can bring your workloads back whenever you have recovered your environment from the disaster that occurred and you are ready to run those workloads on-prem again.

Now there are many more details, but I am not going to share those in this post, I may do a couple of additional blogs at a future time. I hope the above gives a good overview of what the offering will provide. For more details, I would recommend watching the VMworld sessions on this topic (HCI2876, HCI2886, HCI2865). The last thing I want to share though is where the solution will be available, or at least what is being planned. As shown below, the offering should be available in multiple regions soon.

vSphere HA internals: restart placement changes in vSphere 7!

Duncan Epping · May 13, 2020 ·

Frank and I are looking to update the vSphere Clustering deep dive to vSphere 7. While scoping the work I stumbled on to something interesting, and this is the change that was introduced for the vSphere HA restart mechanism,  and specifically the placement of VMs in vSphere 7. In previous releases vSphere HA had a straight forward way of doing placement for VMs when VMs need to be restarted as a result of a failure. In vSphere 7.0 this mechanism was completely overhauled.

So how did it work pre-vSphere 7?

  • HA uses the cluster configuration
  • HA uses the latest compatibility list it received from vCenter
  • HA leverages a local copy of the DRS algorithm with a basic (fake) set of stats and runs the VMs through the algorithm
  • HA receives a placement recommendation from the local algorithm and restarts the VM on the suggested host
  • Within 5 minutes DRS runs within vCenter, and will very likely move the VM to a different host based on actual load

As you can imagine this is far from optimal. So what is introduced in vSphere 7? Well, we introduce two different ways of doing placement for restarts in vSphere 7:

  1. Remote Placement Engine
  2. Simple Placement Engine

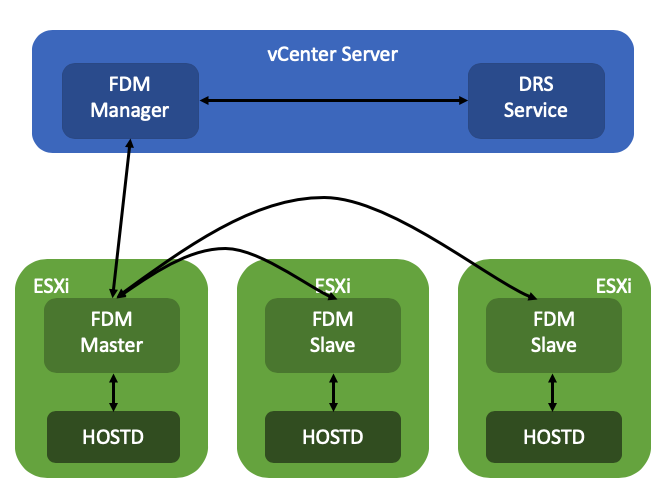
The Remote Placement Engine, in short, is the ability for vSphere HA to make a call to DRS for the recommendation of the placement of a VM. This will take the current load of the cluster, the VM happiness, and all configured affinity/anti-affinity/vm-host affinity rules into consideration! Will this result in a much slower restart? The great thing is that the DRS algorithm has been optimized over the past years and it is so fast that there will not be a noticeable difference between the old mechanism and the new mechanism. Added benefit of course for the engineering team is that they can remove the local DRS module, which means there’s less code to maintain. How this works is that the FDM Master communicated with the FDM Manager which runs in vCenter Server. FDM Manager communicates with the DRS service to request a placement recommendation.

Now some of you will probably wonder what happens when vCenter Server is unavailable, well this is where the Simple Placement Engine comes into play. The team has developed a new placement engine that basically takes a round-robin approach, but does consider of course “must rules” (VM to Host) and the compatibility list. Note, affinity, or anti-affinity rules, are not considered when SPE is used instead of RPE! This is a known limitation, which is considered to be fixed in the future. If a host, for instance, is not connected to the datastore the VM is running on that needs to be restarted than that host is excluded from the list of potential placement targets. By the way, before I forget, version 7 also introduced a vCenter heartbeat mechanism as a result. HA will be heart beating the vCenter Server instance to understand when it will need to resort to the Simple Placement Engine vs the Remote Placement Engine.

I dug through the FDM log to find some proof of these new mechanisms, (/var/log/fdm.log) and found an entry that shows there are indeed two placement engines:

Invoking the RPE + SPE Placement Engine

RPE stands for “remote placement engine”, and SPE for “simple placement engine”. Where Remote of course refers to DRS. You may ask yourself, how do you know if DRS is being called? Well, that is something you can see in the logs in the DRS log files, when a placement request is received, the below entry shows up in the log file:

FdmWaitForUpdates-vim.ClusterComputeResource:domain-c8-26307464

This even happens when DRS is disabled and also when you use a license edition which does not include DRS even, which is really cool if you ask me. If for whatever reason vCenter Server is unavailable, and as a result DRS can’t be called, you will see this mentioned in the FDM log, and as shown below, it will use the Simple Placement Engine’s recommendation for the placement of the VM:

Invoke the placement service to process the placement update from SPE

A cool and very useful small HA enhancement if you ask me for vSphere 7.0!


** Disclaimer: This article contains references to the words master and/or slave. I recognize these as exclusionary words. The words are used in this article for consistency because it’s currently the words that appear in the software, in the UI, and in the log files. When the software is updated to remove the words, this article will be updated to be in alignment. **

Startup intro: SaaS-based backup solution Clumio

Duncan Epping · Apr 6, 2020 ·

Last week I saw an update from one of the Clumio founders on twitter. It reminded me that I had promised to take a look at their product. This week I had a meeting set up with Clumio and we went over their product and how to configure it briefly. Clumio is a SaaS based backup solution that was founded in 2017 by former PernixData, Nutanix, EMC folks. The three founders are Poojan Kumar, Kaustubh Patil, and Woon Jung, and those three you may remember from PernixData. One thing to point out is that they had 3 rounds of funding (~190 million dollars) so far and they came out of stealth around VMworld 2019. Coincidentally they won the Gold award for Best of VMworld in the data protection category, and best of show for the entire show, not bad for a first VMworld. I guess that I have to point out that although I would classify them as backup/recovery today, they are adding new functionality weekly and “backup/recovery” is probably not a fair category, data protection is more appropriate and it would not surprise me if that evolves to data management and protection over time. If you are not a fan of reading, simply head over to my youtube video on Clumio, otherwise, just continue below.

So how does it work conceptually? Well they basically have a SaaS solution, but you will need to install an OVA (they call it a cloud connector) in your environment to connect to the SaaS platform for VMware on-premises and VMware Cloud on AWS. When you connect AWS EBS they use a cloud formation template. This cloud connector is a 4 vCPU/8GB virtual machine that then needs the ability to connect to “the outside world” of course. The Cloud Connector is stateless and requires no updates. You can run this Cloud Connector appliance in multiple clusters, on-prem, or in VMware Cloud on AWS and once they are registered you will see those data sources in your portal.  This is nice as you can see all your data sources across public and private clouds in one single pane of glass. You will have the ability to define “backup schemes” by creating policies. These policies can of course then be associated with objects. These objects can be VMs, Clusters and even vCenter Server instances. This means that if you assign a policy to vCenter Server that every new VM created will inherit the policy automatically. You may wonder, where is your data stored? Your data is stored in S3 buckets that are part of the Clumio SaaS-based platform. Customers are isolated from each other, they will have their own dedicated S3 buckets, and these buckets are created and maintained by Clumio, you as a customer only interact with Clumio! [Read more…] about Startup intro: SaaS-based backup solution Clumio

Install and Configure vSphere Replication with SRM 8.3 on vSphere 7

Duncan Epping · Apr 2, 2020 ·

I haven’t really done much with vSphere Replication and Site Recovery Manager (SRM) in the past years as my main focus has been vSAN. I figured I would get two clusters up and running and install and configure both vSphere Replication as well as SRM on top of vSphere 7. Although the installation and configuration are pretty straight forward, there are a few steps which are important. Below the steps I took to get things up and running.

  • Deploy the vSphere Replication appliance in both clusters
  • Deploy the Site Recovery Manager appliance in both clusters
  • Go to “https://<ip of vSphere Replication appliance>:5480” in first cluster
    • username: root
    • password: what ever you specified!
  • Click on “Configuration Page” link
  • Specify Password of vCenter Server in the Password field
  • Click “Apply Network Settings”
  • Click “Save and Restart Service”
  • Accept the SSL Certificate
  • Repeat the above for the second cluster!
  • Now go to your vSphere H5 Client and wait until the vSphere Replicated tasks are completed
  • Log out of the vSphere H5 Client and log back in for both clusters
  • Now go to the first cluster / vCenter server
  • Now click on “Menu” and then “Site Recovery”
  • Click “open Site Recovery”
  • Click “New Site Pair”
  • Fill out the details of the second vCenter Server
  • Click Next and Connect if you get a security alert and are certain this is the correct vCenter instance
  • Select the correct listed vCenter instance and vSphere Replication appliance
  • Click Next and Finish, now you will see a task within vCenter that states “Connect vSphere Replication Sites”
  • Now you have vSphere Replication running and you can replicate VMs from one location to the other manually if and when desired.

[Read more…] about Install and Configure vSphere Replication with SRM 8.3 on vSphere 7

Creating a vSAN 7.0 Stretched Cluster

Duncan Epping · Mar 31, 2020 ·

A while ago I wrote this article and created this demo showing the creation of a vSAN Stretched Cluster. I bumped into the article/video today when I was looking for something and figured that it is time to recreate the vSAN Stretched Cluster demo. I recorded it today, using vSphere / vSAN 7, and just wanted to share it with you here. Hope you enjoy it.

  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 5
  • Page 6
  • Page 7
  • Page 8
  • Page 9
  • Interim pages omitted …
  • Page 64
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in