• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

BC-DR

Disable the re-registering of HA disabled VMs on other hosts!

Duncan Epping · Jan 24, 2023 ·

Years ago we had various customers that complained about the fact that they had VMs that were disabled for HA and that these VMs would not be re-registered when the host they were registered on would fail. I can understand why you would want the VMs to be re-registered as this makes it easier to power-on those VMs when a host has failed. If the VM would not be re-registered automatically, and the host to which it was registered has failed, you would have to manually register the VM and only then would you be able to power on that VM.

Now, it doesn’t happen too often, but there are also situations where certain VMs are disabled for HA restarts (or powered off) and customers don’t want to have those VMs to be re-registered as these VMs are only allowed to run on one particular host. In that particular case you can simply disable the re-registering of HA disabled VMs through the use of an advanced setting. The advanced setting for this, and the value to use, is the following:

das.reregisterrestartdisabledvms - false

Unexplored Territory Podcast #033 – Introducing VMware Ransomware Recovery, featuring Nabil Quadri!

Duncan Epping · Dec 14, 2022 ·

In episode 033 we spoke with Nabil Quadri about the Ransomware Recovery as a Service solution that VMware recently announced. Nabil discusses how common ransomware attacks are these days, and how customers are struggling to recover from them. He then goes on to explain how VMware Ransomware Recovery is built on the foundation of  VMware Cloud Disaster Recovery, and he goes over the details of the offering and implementation. Listen now: Spotify (https://spoti.fi/3PkTTV7), Apple (https://apple.co/3UQvXdE), or simply use the embedded player below!

VMware announces Ransomware Recovery as a Service and Data Protection vision!

Duncan Epping · Sep 13, 2022 ·

At VMware Explore there was a whole session (CEIB1236US) dedicated to the vision for Data Protection and Ransomware Recovery as a Service. Especially the Ransomware Recovery as a Service had my interest as it is something that keeps coming up with customers. How do I protect my data, and when needed how do recover? Probably a year ago or so I had a conversation with VMware CTO for Cloud Storage and Data (Sazzala) on this topic, and we met up with various customers to gather requirements. Those discussions ultimately led to the roadmap for this new service and new features. Below I am going to summarize what was discussed in this session at VMware Explore, but I would urge you to watch the session as it is very valuable, and it is impossible for me to capture everything.

VMware’s Disaster Recovery as a Service solution is a unique offering as it provides the best of both worlds when it comes to Disaster Recovery. With DR you typically have two options:

  1. Fast recovery, relatively high cost.
    • Traditionally most customers went for this option, they had a “hot standby” environment that provided full capacity in case of emergency. But as this environment is always up and running and underutilized, it is a significant overhead.
  2. Slower recovery, relatively low cost.
    • This is where VMs are replicated to cheap and deep storage and compute resources are limited (if available at all). When a recovery needs to happen, data rehydration is required and as such, it is a relatively slow process.

With VMware’s offering, you now have a 3rd option: Fast recovery, at a relatively low cost! VMware provides the ability to store backups on cheap storage, and then recover (without hydration) directly in a cloud-based SDDC. It provides a lot of flexibility, as you can have a minimum set of hosts constantly running within your prepared SDDC, and scale out when needed during a failure, or you can even create a full SDDC at the time of recovery.

Now, this offering is available in VMware Cloud on AWS in various regions. During the session, the intention was also shared to deliver similar capabilities on Azure VMware Solution, Oracle Cloud VMware Solution, Google Cloud VMware Engine, and/or Alibaba Cloud VMware Service. Basically all global hyper-scalers. Maybe even more important, VMware also discussed additional capabilities that are being worked on. Scaling to tens of thousands of VMs, managing multi-petabytes of storage, providing 1-minute RPO levels, proving multi-VM consistency, having end-to-end SLA observability, providing advanced insights into cost and usage, and probably most important… a full REST API.

All of those enhancements are very useful for those aiming to recover from a disaster, not just natural disasters, but also for Ransomware attacks. Some of you may wonder how common a ransomware attack is, but unfortunately, it is very common. Surveys have revealed that 60% of the surveyed organizations were hit by ransomware in the past 12 months, 92% of those who paid the ransom did not gain full access to the data, and the average downtime was 16 days. Those are some scary numbers in my opinion. Especially the downtime associated with an attack, and the fact that full access was not regained even after paying a ransom.

In general recovery from ransomware is complex as ransomware typically remains undetected for larger periods of time before you are exposed to it. Then when you are exposed you don’t have too many options, you recover to a healthy point in time or you pay the ransom. When you recover, of course, you want to know if the set you are recovering is infected or not. You also want to have some indication of when the environment was infected, as no one wants to go through 3 months of snapshots before you find the right one. That alone would take days, if not weeks, and downtime is extremely expensive. This is where VMware Ransomware Recovery for VMware Cloud DR comes in.

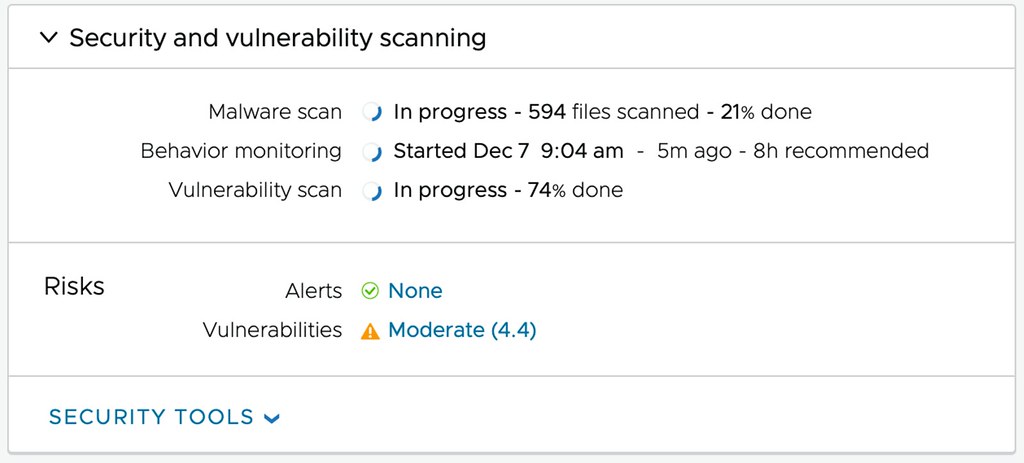
The aim for the VMware Ransomware Recovery for VMware Cloud DR solution is to provide the ability to recover to an Isolated Recovery Environment (including networking). This first of all prevents reinfection at the time of recovery. During the recovery process, the environment is also analyzed by a next-generation anti-virus scanner for known/current threats. Simply to prevent a situation where you recover a snapshot that was infected. What I am even more impressed by is that the plan is to also include a visual indication of when most likely an environment was infected, this is done by providing an insight into the data change rate and entropy. Now, entropy is not a word most non-native speakers are familiar with, I wasn’t, but it refers to the randomness of the data. Both the change rate and the entropy could indicate abnormal patterns, which then could indicate the time of infection and help identify a healthy snapshot to recover!

As mentioned, during recovery the snapshot is scanned by a Next-Gen AV, and of course, when infections are detected they will be reported in the UI. This then provides you the option to discard the recovery and select a different snapshot. Even if no vulnerabilities are found the environment can be powered on fully isolated, providing you the ability to manually inspect before exposing app owners, or end-users, to the environment again.


Now comes the cool part, when you have curated the environment, when you are absolutely sure this is a healthy point in time that was not infected, you have the choice to fallback to your “source” environment or simply remain running in your VMware Cloud while you clean up your “source” site. Before I forget, I’ve been talking about full environments and VMs so far, but of course, it is also the intention to provide the ability to restore files and folders of course! All in all, a very impressive solution that should be available in the near future.

If you are interested in these capabilities and would like to stay informed, please fill out this form: https://forms.office.com/r/yh69Npq7nY.

Nested Fault Domains on a 2-Node vSAN Stretched Cluster, is it supported?

Duncan Epping · Jun 20, 2022 ·

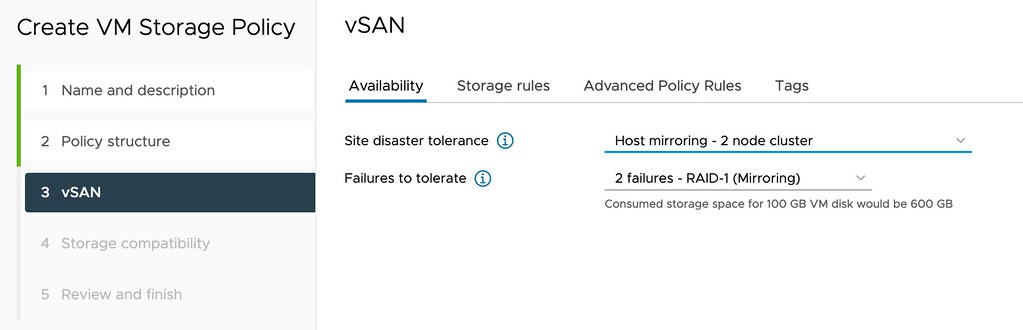
I spotted a question this week on VMTN, the question was fairly basic, are nested fault domains supported on a 2-node vSAN Stretched Cluster? It sounds basic, but unfortunately, it is not documented anywhere, probably because stretched 2-node configurations are not very common. For those who don’t know, with a nested fault domain on a two-node cluster you basically provide an additional layer of resiliency by replicating an object within a host as well. A VM Storage Policy for a configuration like that will look as follows.

This however does mean that you would need to have a minimum of 3 fault domains within your host as well if you want to, this means that you will need to have a minimum of 3 disk groups in each of the two hosts as well. Or better said, when you configure Host Mirroring and then select the second option failures to tolerate the following list will show you the number of disk groups per host you need at a minimum:

  • Host Mirroring – 2 Node Cluster
    • No Data Redundancy – 1 disk group
    • 1 Failure – RAID1 – 3 disk groups
    • 1 Failure – RAID5 – 4 disk groups
    • 2 Failures – RAID1 – 5 disk groups
    • 2 Failures – RAID6 – 6 disk groups
    • 3 Failures – RAID1 – 7 disk groups

If you look at the list, you can imagine that if you need additional resiliency it will definitely come at a cost. But anyway, back to the question, is it supported when your 2-node configuration happens to be stretched across locations, and the answer is yes, VMware supports this.

Unexplored Territory: recovering from a ransomware attack /w Sazzala Reddy!

Duncan Epping · Nov 1, 2021 ·

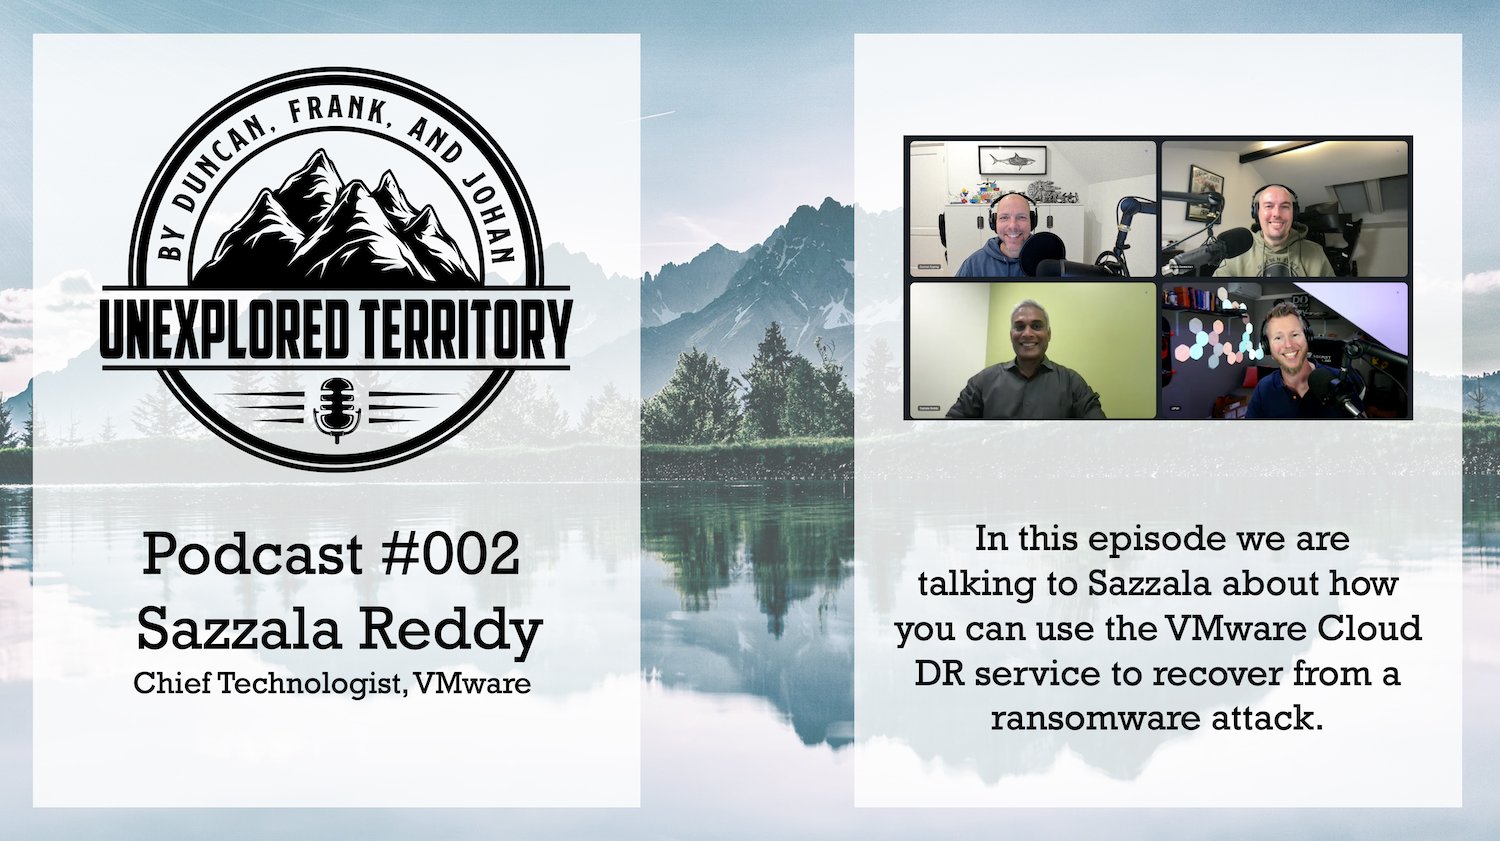
There we go, episode 002 of the Unexplored Territory Podcast was just published. In this episode we talk to Sazzala Reddy. Sazzala is a Chief Technologist at VMware who joined via the Datrium acquisition, where he was the CTO. Before founding Datrium, he was at Dell/EMC, where he came in via the DataDomain acquisition. I think it is fair to say that Sazzala has a heavy data/storage DNA. We discuss Sazzala’s career path, why better is sometimes worse, and we extensively discuss VCDR and the new cloud file system that is being developed. I think it is a very interesting episode and would encourage everyone to give it a listen!

Make sure to follow Sazzala on twitter (https://twitter.com/sazzala) and read his blog post on the VCDR filesystem: https://bit.ly/3CiQoav.

Listen now via Apple Podcasts: https://apple.co/2ZOziDx, Spotify: https://spoti.fi/3BEkFja, Google: https://bit.ly/3Cy3ssF, Overcast: https://overcast.fm/+zyG9k_hks, Website: https://bit.ly/3w70FnV.

  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 3
  • Page 4
  • Page 5
  • Page 6
  • Page 7
  • Interim pages omitted …
  • Page 64
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in