• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

vSphere

vSphere HA reporting not enough failover resources fault with stretched cluster failure scenario

Duncan Epping · Nov 20, 2020 ·

Last few months I had a couple of customers asking why vSphere HA was reporting “not enough failover resources” fault in a stretched cluster failure scenario for virtual machines that are still up and running. Now before I explain why, let’s paint a picture first to make it clear what is happening here. When you run a stretched cluster you can have a scenario where a particular VM (or multiple VMs) are not mirrored/replicated across locations. Now note, with vSAN you can specify for any given VM on a VM level how and if the VM should be available across locations. Typically you would see a VM with RAID-1 across locations, and then RAID-1/5/6 within a location. However, you can also have a scenario where a VM is not replicated across locations, but from a storage point of view only available within a location, this is depicted in the diagram below.
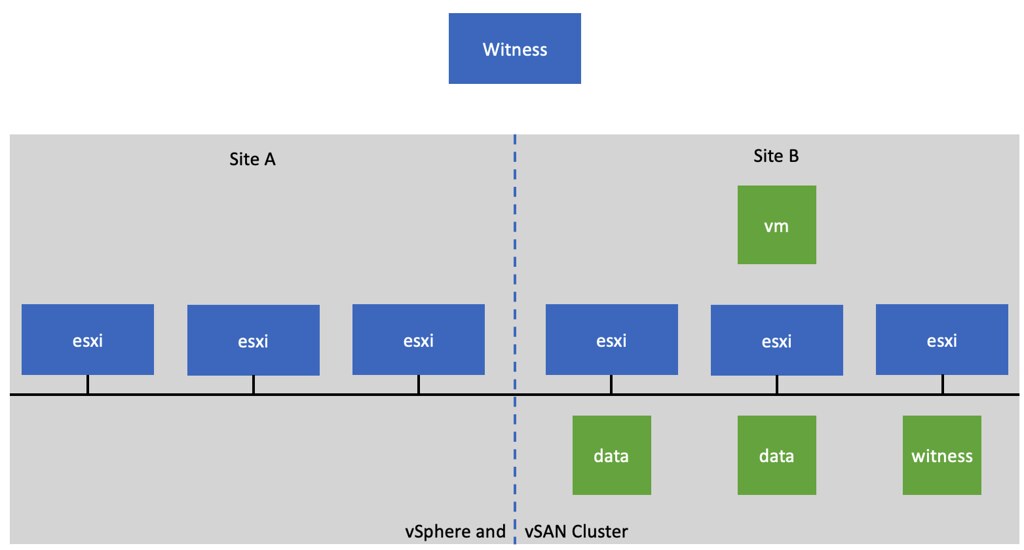
Now in this scenario, when Site A is somehow partitioned from Site B, you will see alarms/errors which indicate that vSphere HA has tried to restart the VM that is located in Site B in Site A and that is has failed as a result of not having enough failover resources.

This, of course, is not the result of not having sufficient failover resources, but it is the result of the fact that Site A does not have access to the required storage components to restart the VM. Basically what HA is reporting is that it doesn’t have the resources which have the ability to restart the impacted VM(s).

Now, if you have paid attention, you will probably wonder why HA tries to restart the VM in the first place, as the VM will still be running in this scenario. Why is it still running? Well the VM isn’t stretched, and this is a partition and not an isolation, which means the isolation response doesn’t kill the VM. So why restart it? Well, as Site A is partitioned from Site B, Site A does not know what the status is of Site B. Site A only knows that Site B is not responding at all, and the only thing it can do is assume the full site has failed. As a result it will attempt a failover for all VMs that were/are running in Site B and were protected by vSphere HA.

Hope that explains why this happens. If you are not sure you understand the full scenario, I recorded a quick five minute video actually walking through the scenario and explaining what happens. You can watch that below, or simply go to youtube.

How to login to the vCLS VMs!?

Duncan Epping · Nov 17, 2020 ·

I was asked this question this week, how you can login to the vCLS VMs. Now before I share the video, I want to mention that I do not encourage people doing this, but as it is documented and supported I do want to provide a simple “how to” for how this works. If you want to login to the vCLS VM, maybe for troubleshooting if needed or for auditing, you can do so by SSH’ing first into your vCenter Server. When logged in to the vCenter Server you run the following command, which then returns the password, this will then allow you to login to the console of the vCLS VM. Again, I do not want to encourage you to do this. Either way, below you find the command for retrieving the password, and a short demo of me retrieving the password and logging in.

/usr/lib/vmware-wcp/decrypt_clustervm_pw.py


Did you know vSphere 7.0 Update 1 also has a Skyline Health Check for vSphere Clustering Services?

Duncan Epping · Nov 6, 2020 ·

I did not know this, but yesterday the PM for vCLS reached out to me and informed me that we now have a Skyline Health Check as well for vSphere Clustering Services. The funny thing is that I actually requested this health check to be added after having a discussion on the topic of vCLS with the PM. Very impressive how fast the engineering team managed to include an additional health check for a brand new feature, this close to the release. I created a short demo, which shows you where you can find the vSphere Skyline Health option in the vSphere Client, and of course, it shows the vCLS Health Check being triggered. If you see the health check triggered, you can as mentioned enable retread mode and disable it again, this will provision a fresh set of vCLS VMs. How you do this you can find in this “considerations blog“, or simply watch the demo I shared here.

Demo Time: How to delete the vCLS VMs

Duncan Epping · Oct 27, 2020 ·

As I have a bunch of questions about how you can delete the vSphere Cluster Service VMs (vCLS VMs) I figured I would create a quick demo. It is pretty straightforward, and it should only be used when people are doing some kind of full cluster maintenance. This demo shows you how to get the VMs deleted by leveraging a vCenter Server Level Advanced setting (config.vcls.clusters.domain-c<identifier>.enabled). I have also written a post that has a bunch of requirements, Q&A, and considerations for the vCLS VMs, if you are interested in that read it here.

Here’s the summary of how to delete the VMs: Go to your vCenter Server object, go to the configure tab, then go to “Advanced Settings”, add the key “config.vcls.clusters.domain-c<identifier>.enabled” and set it to false. The domain “c-number” for your cluster can be found in the URL when you click on the cluster. It should look something like the following, where the bold part is the important bit: https://vcsa-06.rainpole.com/ui/app/cluster;nav=h/urn:vmomi:ClusterComputeResource:domain-c22:4df0badc-1655-40de-9181-3422d6c36a3e/summary. If you want to recreate the VMs, simply set the value to “true” when the deletion task has completed.

Note, if you have a resource pool configuration, enabling “retreat mode” (disabling vCLS)) doesn’t impact resource pools in any shape or form, it just impacts DRS load balancing. Anyway, I hope you find the demo useful.

VMware vSphere Cluster Services (vCLS) considerations, questions and answers.

Duncan Epping · Oct 9, 2020 ·

In the vSphere 7.0 Update 1 release VMware introduced a new service called the VMware vSphere Cluster Services (vCLS). vCLS provides a mechanism that allows VMware to decouple both vSphere DRS and vSphere HA from vCenter Server. Niels Hagoort wrote a lengthy article on this topic here. You may wonder why VMware introduces this, well as Niels states. by decoupling the clustering services (DRS and HA) from vCenter Server via vCLS we ensure the availability of critical services even when vCenter Server is impacted by a failure.

vCLS is a collection of multiple VMs which, over time, will be the backbone for all clustering services. In the 7.0 U1 release a subset of DRS functionality is enabled through vCLS. Over the past week(s) I have seen many questions coming in and I wanted to create a blog with answers to these questions. When new questions or considerations come up, I will add these to the list below.

[Read more…] about VMware vSphere Cluster Services (vCLS) considerations, questions and answers.

  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 8
  • Page 9
  • Page 10
  • Page 11
  • Page 12
  • Interim pages omitted …
  • Page 159
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in