• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

Designing your hardware for Virtual SAN

Duncan Epping · Oct 9, 2013 ·

Over the past couple of weeks I have been watching the VMware VSAN Community Forum with close interest and also twitter. One thing that struck me was the type of hardware people used for to test VSAN on. In many cases this is the type of hardware one would use at home, for their desktop. Now I can see why that happens, I mean something new / shiny and cool is released and everyone wants to play around with it, but not everyone has the budget to buy the right components… And as long as that is for “play” only that is fine, but lately I have also noticed that people are looking at building an ultra cheap storage solution for production, but guess what?

Virtual SAN reliability, performance and overall experience is determined by the sum of the parts

You say what? Not shocking right, but something that you will need to keep in mind when designing a hardware / software platform. Simple things can impact your success, first and foremost check the HCL, and think about components like:

  • Disk controller
  • SSD / PCIe Flash
  • Network cards
  • Magnetic Disks

Some thoughts around this, for instance the disk controller. You could leverage a 3Gb/s on-board controller, but when attaching lets say 5 disks to it and a high performance SSD do you think it can still cope or would a 6Gb/s PCIe disk controller be a better option? Or even leverage 12Gb/s that some controllers offer for SAS drives? Not only can this make a difference in terms of number of IOps you can drive, it can also make a difference in terms of latency! On top of that, there will be a difference in reliability…

I guess the next component is the SSD / Flash device, this one is hopefully obvious to each of you. But don’t let these performance tests you see on Tom’s or Anandtech fool you, there is more to an SSD then just sheer IOps. For instance durability, how many writes per day for X years life can your SSD handle? Some of the enterprise grades can handle 10 full writes or more per day for 5 years. You cannot compare that with some of the consumer grade drives out there, which obviously will be cheaper but also will wear out a lot faster! You don’t want to find yourself replacing SSDs every year at random times.

Of course network cards are a consideration when it comes to VSAN. Why? Well because I/O will more than likely hit the network. Personally, I would rule out 1GbE… Or you would need to go for multiple cards and ports per server, but even then I think 10GbE is the better option here. Most 10GbE are of a decent quality, but make sure to check the HCL and any recommendations around configuration.

And last but not least magnetic disks… Quality should always come first here. I guess this goes for all of the components, I mean you are not buying an empty storage array either and fill it up with random components right? Think about what your requirements are. Do you need 10k / 15k RPM, or does 7.2k suffice? SAS vs SATA vs NL-SATA? Also, keep in mind that performance comes at a cost (capacity typically). Another thing to realize, high capacity drives are great for… yes adding capacity indeed, but keep in mind that when IO needs to come from disk, the number of IOps you can drive and your latency will be determined by these disks. So if you are planning on increasing the “stripe width” then it might also be useful to factor this in when deciding which disks you are going to use.

I guess to put it differently, if you are serious about your environment and want to run a production workload then make sure you use quality parts! Reliability, performance and ultimately your experience will be determined by these parts.

<edit> Forgot to mention this, but soon there will be “Virtual SAN” ready nodes… This will make your life a lot easier I would say.

</edit>
Where is that Yellow-Bricks dude hanging out during VMworld?

Duncan Epping · Oct 8, 2013 ·

Some people have been asking what my agenda looks like, when my sessions are and if there are any specific social events I am likely to attend… Well here you go:

My sessions / group discussions:

  • Monday, Oct 14, 12:00 – 13:30 – TAM Day, Birds of a Feather Lunch
  • Monday, Oct 14, 13:45 – 14:30 – TAM Day, vCloud – Ask the experts sessions
  • Tuesday, Oct 15, 11:00 – 12:00 – Hall 8.0, Room B1 – vSphere HA Group Discussion
  • Tuesday, Oct 15, 17:00 – 18:00 – Hall 8.0, Room F2 – BCO4872 – Operating and Architecting a vSphere Metro Storage Cluster Based Infrastructure (sold out!)
  • Thursday, Oct 17, 13:30 – 14:30 – Hall 8.0, Room E3 – BCO4872 – Operating and Architecting a vSphere Metro Storage Cluster Based Infrastructure (repeat)

Social events I am may attend, and no… unfortunately I cannot get you tickets to these:

  • Sunday, Oct 13, evening: nothing planned
  • Monday, Oct 14, evening: VMUG party, VMware Ireland, Pernix Data
  • Tuesday, Oct 15, evening: CTO party, VMware Benelux, Veeam
  • Wednesday, Oct 16, evening: VMworld party

Hoping I will be able to attend the following sessions / discussion groups:

  • Wednesday, Oct 16, 12:30 – 13:30 – Hall 8.0, Room C1 – Group Discussion: Stretched Clusters with Lee Dilworth
  • Wednesday, Oct 16, 12:30 – 13:30 – Hall 8.0, Room F2 – Session: Performance and Capacity Management of DRS Clusters with Anne and Ganesha (both VMware engineers)
  • Wednesday, Oct 16, 14:00 – 15:00 – Hall 8.0, Room C2 – Group Discussion: VSAN with Cormac Hogan
  • Wednesday, Oct 16, 15:30 – 16:30 – Hall 8.0, Room C2 – Group Discussion: Disaster Recovery and Replication with Ken Wernerburg
  • Wednesday, Oct 16, 15:30 – 16:30 – Hall 8.0, Room D4 – Session: Storage DRS: Deep Dive and Best Practices to Suit Your Storage Environments with Mustafa and Sachin (both VMware engineers)
  • Wednesday, Oct 16, 17:00 – 18:00 – Hall 8.0, Room A3 – Session: Building a google-like infrastructure for the enterprise with Raymon Epping
  • Thursday, Oct 17, 9:00 – 10:00 – Hall 8.0, Room C1 – Group Discussion: Software Defined Storage with Rawlinson Rivera and Cormac Hogan
  • Thursday, Oct 17, 10:30 – 11:30 – Hall 8.0, Room G3 – Session: DRS: New Features, Best Practices and Future Directions (VMware engineer

HA Futures: Pro-active response

Duncan Epping · Oct 4, 2013 ·

We all know (at least I hope so) what HA is responsible for within a vSphere Cluster. Although it is great that vSphere HA responds to a failure of a host / VM / application and even in some cases your storage device; wouldn’t it be nice if vSphere HA could pro-actively respond to conditions which might lead to a failure? That is what we want to discuss in this article.

What we are exploring right now is the ability for HA to avoid unplanned downtime. HA would detect specific (health) conditions that could lead to catastrophic failures and pro-actively move virtual machines of that host. You could for instance think of a situation where 1 out of 2 storage paths goes down. Although not directly impacting the machines from an availability perspective, it could be catastrophic if that second path goes down. So in order to avoid ending up in this situation vSphere HA would vMotion all the virtual machines to a host which does not have a failure.

This could of course also apply to other components like networking or even memory or CPU. You could potentially have a memory dimm which is reporting specific issues that could impact availability, this in its turn could then trigger HA to pro-actively move all potentially impacted VMs to a different host.

A couple of questions we have for you:

  1. When such partial host failures occur today, how do you address these conditions? When do you bring the host back online?
  2. What level of integration do you expect with management tools? In other words, should we expose an API that your management solution can consume, or do you prefer this to be a stand-alone solution using a CIM provider for instance?
  3. Should HA treat all health conditions the same? I.e., always evacuate all VMs from an “unhealthy” host?
  4. How would you like HA to compare two conditions? E.g., H1 fan failure, H2 network path failure?

Please chime in,

Virtual SAN news flash pt 1

Duncan Epping · Oct 3, 2013 ·

I had a couple of things I wanted to write about with regards to Virtual SAN which I felt weren’t beefy enough to dedicate a full article to so I figured I would combine a couple of news worthy items and create a Virtual SAN news flash article / series.

  • I was playing with Virtual SAN last week and I noticed something I hadn’t noticed yet… I was running vSphere with an Enterprise license and I added the Virtual SAN license for my cluster. After adding the Virtual SAN license all of a sudden I had the Distributed Switch capability on the cluster I had VSAN licensed. Now I am not sure what this will look like when VSAN will go GA, but for now those who want to test with VSAN and want to use the Distributed Switch you can. Use the Distributed Switch to guarantee bandwidth (leveraging Network IO Control) to Virtual SAN when combining different types of traffic like vMotion / Management / VM traffic on a 10GbE pair. I would highly recommend to start playing around with this and get experienced. Especially because vSphere HA traffic and VSAN traffic are combined on a single NIC pair and you do not want HA traffic to be impacted by replication traffic.
  • The Samsung SM1625 SSD series (eMLC) has been certified for Virtual SAN. It comes in sizes ranging between 100Gb and 800GB and can do up to 120k IOps random read… Nice to see the list of supported SSDs expanding, will try to get my hands on one of these at some point to see if I can do some testing.
  • Most people by now are aware of the challenges there were with the AHCI controller. I was just talking with one of the VSAN engineers who mentioned that they have managed to do a full root cause analysis and pinpoint the root of this problem. Currently there is a team working on solving it and things are looking good and hopefully soon a new driver will be released, when we do I will let you guys know as I realize that many use these controllers in their home-lab.

Virtual SAN and Data Locality/Gravity

Duncan Epping · Sep 30, 2013 ·

I was reading this article by Michael Webster about the benefit of Jumbo Frames. Michael was testing what the impact was from both an IOps and latency perspective when you run Jumbo Frames vs non-Jumbo Frames. Michael saw a clear benefit:

  • Higher IOps
  • Lower latency
  • Lower CPU utilization

I would highly recommend reading Michael’s full article for the details, I don’t want to steal his thunder. Now what was most interesting is the following quote, I highly regard Michael he is a smart guy and typically spot-on:

I’ve heard reports that some people have been testing VSAN and seen no noticeable performance improvement when using Jumbo Frames on the 10G networks between the hosts. Although I don’t have VSAN in my lab just yet my theory as to the reason for this is that the network is not the bottleneck with VSAN. Most of the storage access in a VSAN environment will be local, it’s only the replication traffic and traffic when data needs to be moved around that will go over the network between VSAN hosts.

As I said, Michael is a smart guy and as I’ve seen various people asking questions around this and it isn’t a strange assumption to make that with VSAN most IO will be local, I guess this is kind of the Nutanix model. But VSAN is no Nutanix. VSAN takes a different approach, a completely different approach and this is important to realize.

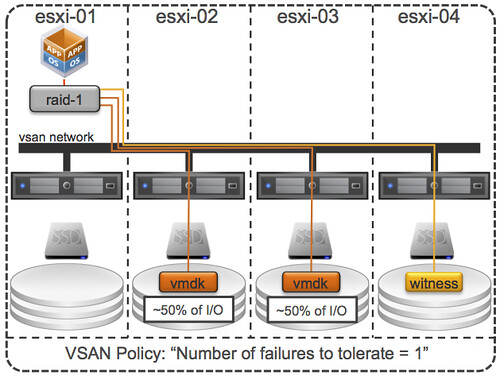
I guess with a very small cluster of 3 nodes Michael chances of IO being local are bigger, but even then IO will not only be local at a minimum 50% (when failures to tolerate is set to 1) due to the data mirroring. So how does VSAN handle this, what are some of the things to keep in mind, lets starts with some VSAN principles:

  • Virtual SAN uses an “object model”, objects are stored on 1 or multiple magnetic disks and hosts.
  • Virtual SAN hosts can access “objects” remotely, both read and write.
  • Virtual SAN does not have the concept of data locality / gravity, meaning that the object does not follow the virtual machine, reason for this is that moving data around is expensive from a resource perspective.
  • Virtual SAN has the capability to read from multiple mirror copies, meaning that if you have 2 mirror copies IO will be distributed equally.

What does this mean? First of all, lets assume you have an 8 host VSAN cluster. You have a policy configured for availability: N+1. This means that the objects (virtual disks) will be on two hosts (at a minimum). What about your virtual machine from a memory and CPU point of view? Well it could be on any of those 8 hosts. With DRS being envoked every 5 minutes at a minimum I would say that chances are bigger that the virtual machine (from a CPU/Memory) resides on one of the 6 hosts that does not hold the objects (virtual disk). In other words, it is likely that I/O (both reads and writes) are being issued remote.

From an I/O path perspective I would like to re-iterate that both mirror copies can and will serve I/O, each would serve ~50% of the I/O. Note that each host has a read cache for that mirror copy, but blocks in read cache are only stored once, this means that each host will “own” a set of blocks and will serve data for those be it from cache or be it from spindles. Easy right?

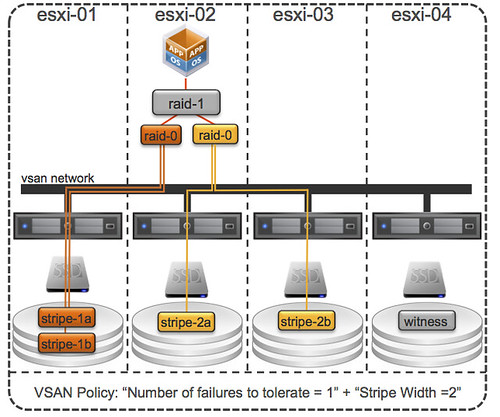
Now just imagine you have configured your “host failures” policy set to 2. I/O can now come from 3 hosts, at a minimum. And why do I say at a minimum? Because when you have the stripe width configured or for whatever reason striping goes across hosts instead of disks (which is possible in certain scenarios) then I/O can come from even more hosts… VSAN is what I would call a true fully distributed solution! Below is an example of “number of failures” set to 1 and “stripe width” set to 2, as can be seen there are 3 hosts that are holding objects.

Lets reiterate that. When you define “host failures” as 1 and stripe width as 1 then VSAN can still, when needed, stripe across multiple disks and hosts. When needed, meaning when for instance the size of a VMDK is larger than a single disk etc.

Now lets get back to the original question Michael asked himself, does it make sense to use Jumbo Frames? Michael’s tests clearly showed that it does, in his specific scenario that is of course. I have to agree with him that when (!!) properly configured it will definitely not hurt, so the question is should you always implement this? I guess if you can guarantee implementation consistency, then conducts tests like Michael did. See if it benefits you, and if it lowers latency and increase IOps I can only recommend to go for it.


PS: Michael mentioned that even when mis-configured it can’t hurt, well there were issues in the past… although they are solved now, it is something to keep in mind.

  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 176
  • Page 177
  • Page 178
  • Page 179
  • Page 180
  • Interim pages omitted …
  • Page 502
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in