• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

Startup introduction: Springpath

Duncan Epping · Feb 19, 2015 ·

Last week I was briefed by Springpath and they launched their company officially yesterday, although they have been around for a long time. Springpath was founded by Mallik Mahalingam and Krishna Yadappanavar. For those who don’t know them, Mallik was responsible for VXLAN (See the IETF draft) and Krishna was one of the folks who was responsible for VMFS. (Together with Satyam who started Pernix Data) I believe it was early 2013 or end of 2012 when Mallik reached out to me and he wanted to validate some of his thinking around the software defined storage space, I agreed to meet up and we discussed the state at that time and where some of the gaps were. Since May 2012 they operated in stealth (under the name Storvisor) and landed a total of 34 million dollars from investors like Sequoia, NEA and Redpoint. Well established VC names indeed, but what did they develop?

Springpath is what most folks would refer to as a Server SAN solution, some may also refer to it as “hyper-converged”. I don’t label them as hyper-converged as Springpath doesn’t sell a hardware solution, they sell software and have a strict hardware compatibility list. The list of server vendors on the HCL seemed to cover the majority of big players out there though, I was told Dell, HP, Cisco and SuperMicro are on the list and that others are being worked on as we speak. This approach offers a bit more flexibility according to Springpath for customers as they can chose their own preferred vendor and leverage the server vendor relationship they already have for discounts but also maintain similar operational processes.

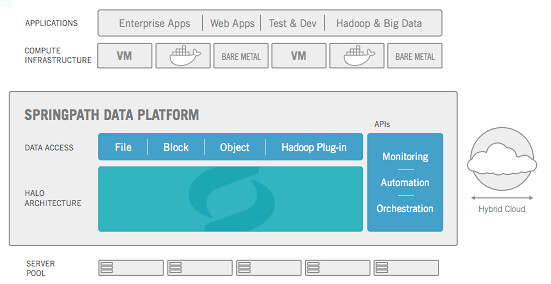
Springpath’s primary focus in the first release is vSphere, which knowing the background of these guys makes a lot of sense, and comes in the shape of a virtual appliance. This virtual appliance is installed on top of the hypervisor and grabs local spindles and flash. With a minimum of three nodes you then can create a shared datastore which is served back to vSphere as an NFS mount. There are of course also plans to support Hyper-V and when they do the appliance will provide SMB capabilities and for KVM it will use NFS. But that is on the roadmap right now, but not too far out according to Mallik. (Note that support for Hyper-V, KVM etc will all be released in a different version. KVM and Docker is in Beta as we speak, if you are interested go to their website and drop them an email!) There is even talk about supporting the Springpath solution to run as a Docker container and providing shared storage for Docker itself. All these different platforms should be able to leverage the same shared data platform according to Springpath, the diagram below shows this architecture.
They demonstrated the configuration / installation of their stack and I must say I was impressed with how simple it was. They showed a simple UI which allowed them to configure the IP details etc, but they also showed how they could simply drop a JSON file in there with all the config details which would then be used to deploy the storage environment. When fully configured the whole environment can be managed from the Web Client, no need for a separate UI or anything like that. All integrated within the Web Client, and for Hyper-V and other platforms they had similar plans… no separate client but all manageable through the familiar interfaces those platforms already offer. [Read more…] about Startup introduction: Springpath
vSphere 6.0: Breaking Large Pages…

Duncan Epping · Feb 17, 2015 ·

When talking about Transparent Page Sharing (TPS) one thing that comes up regularly is the use of Large Pages and how that impacts TPS. As most of you hopefully know TPS does not collapse large page. However, when there is memory pressure you will see that large pages are broken up in to small pages and those small pages can then be collapsed by TPS. ESXi does this to prevent other memory reclaiming techniques, which have way more impact on performance, to kick in. You can imagine that fetching a memory page from a swap file on a spindle will take significantly longer than fetching a page from memory. (Nice white paper on the topic of memory reclamation can be found here…)

Something that I have personally ran in to a couple of times is the situation where memory pressure goes up so fast that the different states at which certain memory reclaiming techniques are used are crossed in a matter of seconds. This usually results in swapping to disk, even though large pages should have been broken up and collapsed where possible by TPS or memory should have been compressed or VMs ballooned. This is something that I’ve discussed with the respective developers and they came up with a solution. In order to understand what was implemented, lets look at how memory states were defined in vSphere 5. There were 4 memory states namely High (100% of minFree), Soft (64% of minFree), Hard (32% of minFree) and Low (16% of minFree). What does that mean % of minFree mean? Well if minFree is roughly 10GB for you configuration then the Soft for instance is reached when there is less then 64% of minFree available which is 6.4GB of memory. For Hard this is 3.2GB and so on. It should be noted that the change in state and the action it triggers does not happen exactly at the percentage mentioned, there is a lower and upper boundary where transition happens and this was done to avoid oscillation.

With vSphere 6.0 a fifth memory state is introduced and this state is called Clear. Clear is 100% of minFree and High has been redefined as 400% of MinFree. When there is less then High (400% of minFree) but more then Clear (100% of minFree) available then ESXi will start pre-emptively breaking up large pages so that TPS (when enabled!) can collapse them at next run. Lets take that 10GB as minFree as an example again, when you have between 30GB (High) and 10GB (Clear) of free memory available large pages will be broken up. This should provide the leeway needed to safely collapse pages (TPS) and avoid the potential performance decrease which the other memory states could introduce. Very useful if you ask me, and I am very happy that this change in behaviour, which I requested a long time ago, has finally made it in to the product.

Those of you who have been paying attention the last months will know that by default inter VM transparent page sharing is disabled. If you do want to reap the benefits of TPS and would like to leverage TPS in times of contention then enabling it in 6.0 is pretty straight forward. Just go to the advanced settings and set “Mem.ShareForceSalting” to 0. Do note that there are security risks potentially when doing this, and I recommend to read the above article to get a better understand of those risks.

** update – originally I was told that High was 300% of minFree, looking at my hosts today it seems that High is actually 400% **

Virtual SAN and ESXTOP in vSphere 6.0

Duncan Epping · Feb 12, 2015 ·

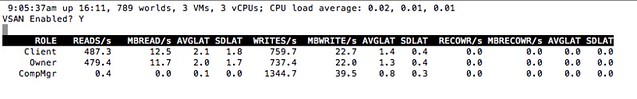
Today I was fiddling with ESXTOP to see if anything was new for vSphere 6.0. Considering the massive number of metrics it already holds it is difficult to find things which stand out / are new. One thing did stick out though which is a new display for Virtual SAN.I haven’t found much detail around this new section in ESXTOP to be honest, but then again I guess most of it speaks for itself. If you are in ESXTOP and press “x” then you will go to the VSAN screen. Now when you press “f” you have the option to add “fields”, I enabled all and the below is the result:

Virtual SAN and ESXTOP

It isn’t a huge amount of detail yet, but being able to see the number of reads, writes and average latency is useful for sure per host. Also what has my interest is “RECOWR/s” and “MBRECOWR/s”. This refers to “recovery writes”, which is the resync of components which were somehow impacted by a failure. If for whatever reason RVC or the VSAN Observer is unavailble then it may be worth peaking at ESXTOP to see what is going on.

HP ConvergedSystem 200–HC EVO:RAIL available now!

Duncan Epping · Feb 11, 2015 ·

Yesterday I was informed by the EVO:RAIL team that the HP ConvergedSystem 200–HC EVO:RAIL is available (shipping) as of this week. I haven’t seen much around additional pieces HP is including, but I was told though that they are planning to integrate HP One View. HP One View is a management/monitoring solution that gives you a great high level overview of the state of your systems but at the same time enables you to dive deep when required. Depending on the version included HP One View can also do things like Firmware Management, which is very useful in a Virtual SAN environment if you ask me. I know though that many people have been waiting for HP to start shipping as it appears to be a preferred vendor for many customers. In terms of configuration, the HP solution is very much similar to what we have already seen out there:

  • 4 nodes in 2U each containing:
    • 2 x Intel® E5-2620 v2 six-core CPUs
    • 192 GB memory
    • 1 x SAS 300 GB 10k rpm drive ESXi boot device
    • 3 x SAS 1.2 TB 10k rpm drive (VSAN capacity tier)
    • 1 x 400 GB MLC enterprise-grade SSD (VSAN performance tier)
    • 1 x H220 host bus adapter (HBA) pass-through controller
    • 2 x 10GbE NIC ports
    • 1 x 1GbE IPMI port for remote (out-of-band) management

As soon as I find out more around integration of other components I will let you folks know.

What is new for Storage DRS in vSphere 6.0?

Duncan Epping · Feb 9, 2015 ·

Storage DRS must be one of the most under-appreciated features that is part of vSphere. For whatever reason it doesn’t get the airtime it deserves, not even from VMware folks which is a shame if you ask me. I was reading the What’s New material for vSphere 6.0 and I noticed that the “What is new for Storage DRS in vSphere 6.0” was completely missing. I figured I would do a quick write up of what has been improved and introduced for SDRS in 6.0 as some of the enhancements are quite significant! Lets start with a list and then look at these enhancements in more detail:

  • Deep integration with vSphere APIs for Storage Awareness (VASA)
  • Site Recovery Manager integration
  • vSphere Replication integration
  • Integration with Storage Policy Based Management

Lets start with the top one, deep integration with vSphere APIs for Storage Awareness (VASA) as that is the biggest improvement if you ask me. What the integration with VASA results in is fairly straight forward, when the VASA plugin for your storage system is configured then Storage DRS will understand what capabilities are enabled on your storage system and more specific your datastores. For example: when using Storage DRS previously on a deduplicated datastore it could happen that the migration initiated by Storage DRS had a negative result on the total available capacity on your storage system. This would be caused by the fact that the deduplication ratio was lower on the destination then it was on the source. Not a very pleasant surprise you can imagine. Also when for instance VMs are snapshotted from a storage system point of view or datastores are replicated… you can imagine that there would be an impact when moving a VM around in that scenario. With 6.0 Storage DRS is capable of understanding:

  • Array-based thin-provisioning
  • Array-based deduplication
  • Array-based auto-tiering
  • Array-based snapshot
  • Array-based replication

I guess you get the drill, SDRS is now fully capable of understanding the array capabilities and will make balancing decisions taking these capabilities in to consideration. For instance in the case of replication, when replication is enabled and your datastore is part of a consistency group then SDRS will ensure that the VM is only migrated to a datastore which belongs to the same consistency group! For deduplication this is the opposite by the way, in this case SDRS will be informed about which datastores belong to which deduplication domains and when datastores belong to the same domain it will know that moving between those datastores will have little to no effect on capacity. Depending on the level of detail the storage vendor provides through VASA SDRS will even be aware of how efficient the deduplication process is for a given datastore. (Not a VASA requirement, rather a recommendation so results may vary per vendor implementation) Auto-tiering is also an interesting one as this is something that comes up regularly. In this scenario with previous versions of SDRS it could happen that SDRS was moving VMs while the auto-tier array was just promoting or demoting blocks to a lower or higher tier. As you can imagine not a desired scenario and with the VASA integration this can be prevented from happening.

Second big thing is Site Recovery Manager and vSphere Replication integration. I already mentioned the consistency group awareness, of course this is also part of the SRM integration and when VMs are protected by SRM then SDRS will make sure that those VMs are only moved within their consistency group. If for whatever reason there is no way to move within a consistency group then SDRS as a second option can move VMs between datastores which are part of the same SRM Protection Group. Note that this could have an impact though on your workloads! SDRS of course will never automatically move a VM from a replicated to a non-replicated datastore. In fact, there is a strict hierarchy of what type of moves can be recommended:

  1. Moves within the same consistency group
  2. Moves across consistency groups, but within the same protection group
  3. Moves across protection groups
  4. Moves from a replicated datastore to non-replicated

Note that SDRS will try option 1 first, if it fails, will try option 2, if that fails will try option 3, and so on. Under no circumstances is a recommendation in the category of 2, 3 or 4 executed automatically. You will receive a warning after which you can manually apply the recommendation. This is done to ensure the administrator has full control and full awareness of the migration and can apply it during maintenance or during non-peak hours.

With regards to vSphere Replication also a lot has changed. So far there was no support for vSphere Replication enabled VMs to be part of an SDRS datastore cluster but with 6.0 it is fully supported. As of 6.0 Storage DRS will recognize replica VMs (which are replicated using vSphere Replication) and thresholds have been exceeded then SDRS will query vSphere Replication and will be able to migrate replicas to solve the resource constraint.

Up next the integration with Storage Policy Based Management. In the past when you had different tiers of datastores as part of the same Datastore Cluster then SDRS could potentially move a VM which was assigned policy “gold” to a datastore which was associated with a “silver” policy. With vSphere 6.0, SDRS is aware of storage policies in SPBM and will only move or place VMs to a datastore that can satisfy that VM’s storage policy.

Oh and before I forget, there is also the introduction of IOPS reservations on a per virtual disk level. This isn’t really part of Storage DRS but a function of the mClock scheduler and integrated with Storage IO Control and SDRS where needed. It isn’t available in the UI even in this release, only exposed through the VIM API so I doubt many of you will use it… figured though I would mention it already, and I will do a deeper write up later this week probably.

  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 138
  • Page 139
  • Page 140
  • Page 141
  • Page 142
  • Interim pages omitted …
  • Page 502
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in