I had a discussion with Benjamin Ulsamer at VMworld and he had a question about the state of a host when both the management network and storage network was isolated. My answer was that in that case the host will be reported as “dead” as there is no “network heartbeat” and no “datastore heartbeat”. (more info about heartbeating here) Funny thing is when you look at the log files you do see isolated instead of dead. Why is that? Before we answer it lets go through the log files and paint the picture:
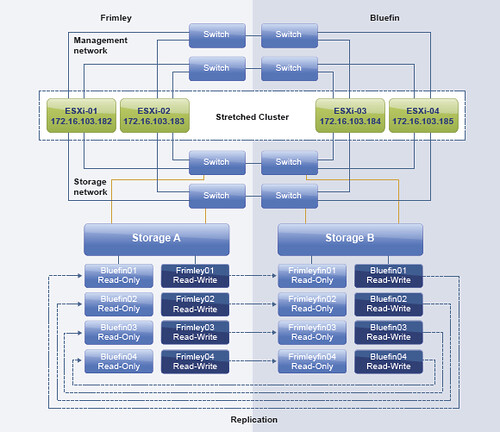
Two hosts (esx01 and esx02) with a management network and an iSCSI storage network. vSphere 5.0 is used and Datastore Heartbeating is configured. For whatever reason for the network of esx02 is isolated (both storage and management as it is a converged environment. So what can you see in the log files?
Lets look at “esx02” first:
- 16:08:07.478Z [36C19B90 info ‘Election’ opID=SWI-6aace9e6] [ClusterElection::ChangeState] Slave => Startup : Lost master
- At 16:08:07 the network is isolated
- 16:08:07.479Z [FFFE0B90 verbose ‘Cluster’ opID=SWI-5185dec9] [ClusterManagerImpl::CheckElectionState] Transitioned from Slave to Startup
- The host recognizes it is isolated and drops from Slave to “Startup” so that it can elect itself as master to take action
- 16:08:22.480Z [36C19B90 info ‘Election’ opID=SWI-6aace9e6] [ClusterElection::ChangeState] Candidate => Master : Master selected
- The host has elected itself as master
- 16:08:22.485Z [FFFE0B90 verbose ‘Cluster’ opID=SWI-5185dec9] [ClusterManagerImpl::CheckHostNetworkIsolation] Waited 5 seconds for isolation icmp ping reply. Isolated
- Can I ping the isolation address?
- 16:08:22.488Z [FFFE0B90 info ‘Policy’ opID=SWI-5185dec9] [LocalIsolationPolicy::Handle(IsolationNotification)] host isolated is true
- No I cannot, and as such I am isolated!
- 16:08:22.488Z [FFFE0B90 info ‘Policy’ opID=SWI-5185dec9] [LocalIsolationPolicy::Handle(IsolationNotification)] Disabling execution of isolation policy by 30 seconds.
- Hold off for 30 seconds as “das.config.fdm.isolationPolicyDelaySec” was configured
- 16:08:52.489Z [36B15B90 verbose ‘Policy’] [LocalIsolationPolicy::GetIsolationResponseInfo] Isolation response for VM /vmfs/volumes/a67cdaa8-9a2fcd02/VMWareDataRecovery/VMWareDataRecovery.vmx is powerOff
- There is a VM with an Isolation Response configured to “power off”
- 16:10:17.507Z [36B15B90 verbose ‘Policy’] [LocalIsolationPolicy::DoVmTerminate] Terminating /vmfs/volumes/a67cdaa8-9a2fcd02/VMWareDataRecovery/VMWareDataRecovery.vmx
- Lets kill that VM!
- 16:10:17.508Z [36B15B90 info ‘Policy’] [LocalIsolationPolicy::HandleNetworkIsolation] Done with isolation handling
- And it is gone, done with handling the isolation
Lets take a closer look at “esx01”, what does this host see with regards to the management network and storage network isolation of “esx02”:
- 16:08:05.018Z [FFFA4B90 error ‘Cluster’ opID=SWI-e4e80530] [ClusterSlave::LiveCheck] Timeout for slave @ host-34
- The host is not reporting itself any longer, the heartbeats are gone…
- 16:08:05.018Z [FFFA4B90 verbose ‘Cluster’ opID=SWI-e4e80530] [ClusterSlave::UnreachableCheck] Beginning ICMP pings every 1000000 microseconds to host-34
- Lets ping the host itself, it could be the FDM agent is dead.
- 16:08:05.019Z [FFFA4B90 verbose ‘Cluster’ opID=SWI-e4e80530] Reporting Slave host-34 as FDMUnreachable
- 16:08:05.019Z [FFD5BB90 verbose ‘Cluster’] ICMP reply for non-existent pinger 3 (id=isolationAddress)
- As it is just a 2 node cluster, lets make sure I am not isolated myself, I got a reply so I am not isolated!
- 16:08:10.028Z [FFFA4B90 verbose ‘Cluster’ opID=SWI-e4e80530] [ClusterSlave::UnreachableCheck] Waited 5 seconds for icmp ping reply for host host-34
- 16:08:14.035Z [FFFA4B90 verbose ‘Cluster’ opID=SWI-e4e80530] [ClusterSlave::PartitionCheck] Waited 15 seconds for disk heartbeat for host host-34 – declaring dead
- There is also no datastore heartbeat so the host must be dead. (Note that it cannot see the difference between a fully isolated host and a dead host when using IP based storage on the same network.)
- 16:08:14.035Z [FFFA4B90 verbose ‘Cluster’ opID=SWI-e4e80530] Reporting Slave host-34 as Dead
- It is officially dead!
- 16:08:14.036Z [FFE5FB90 verbose ‘Invt’ opID=SWI-42ca799] [InventoryManagerImpl::RemoveVmLocked] marking protected vm /vmfs/volumes/a67cdaa8-9a2fcd02/VMWareDataRecovery/VMWareDataRecovery.vmx as in unknown power state
- We don’t know what is up with this VM, power state unknown…
- 16:08:14.037Z [FFE5FB90 info ‘Policy’ opID=SWI-27099141] [VmOperationsManager::PerformPlacements] Sending a list of 1 VMs to the placement manager for placement.
- We will need to restart one VM, lets provide its details to the Placement Manager
- 16:08:14.037Z [FFE5FB90 verbose ‘Placement’ opID=SWI-27099141] [PlacementManagerImpl::IssuePlacementStartCompleteEventLocked] Issue failover start event
- Issue a failover event to the placement manager.
- 16:08:14.042Z [FFE5FB90 verbose ‘Placement’ opID=SWI-e430b59a] [DrmPE::GenerateFailoverRecommendation] 1 Vms are to be powered on
- Lets generate a recommendation on where to place the VM
- 16:08:14.044Z [FFE5FB90 verbose ‘Execution’ opID=SWI-898d80c3] [ExecutionManagerImpl::ConstructAndDispatchCommands] Place /vmfs/volumes/a67cdaa8-9a2fcd02/VMWareDataRecovery/VMWareDataRecovery.vmx on __localhost__ (cmd ID host-28:0)
- We know where to place it!
- 16:08:14.687Z [FFFE5B90 verbose ‘Invt’] [HalVmMonitor::Notify] Adding new vm: vmPath=/vmfs/volumes/a67cdaa8-9a2fcd02/VMWareDataRecovery/VMWareDataRecovery.vmx, moId=12
- Lets register the VM so we can power it on
- 16:08:14.714Z [FFDDDB90 verbose ‘Execution’ opID=host-28:0-0] [FailoverAction::ReconfigureCompletionCallback] Powering on vm
- Power on the impacted VM
That is it, nice right… and is just a short version of what is actually in the log files. It contains a massive amount of details! Anyway, back to the question… if not already answered, the remaining host in the cluster sees the isolated host as dead as there is no:
- network heartbeat
- response to a ping to the host
- datastore heartbeat
The only thing the master can do at that point is to assume the “isolated” host is dead.
** Disclaimer: This article contains references to the words master and/or slave. I recognize these as exclusionary words. The words are used in this article for consistency because it’s currently the words that appear in the software, in the UI, and in the log files. When the software is updated to remove the words, this article will be updated to be in alignment. **