• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

VMware Cloud Foundation

vSAN Stretched: Why is the witness not part of the cluster when the link between a data site and the witness fails?

Duncan Epping · Jun 25, 2024 ·

Last week I received a question about vSAN Stretched which had me wondering for a while what on earth was going on. The person who asked this question was running through several failure scenarios, some of which I have also documented in the past here. The question I got is what is supposed to happen when I have the following scenario as shown in the diagram and the link between the preferred site (Site A) and the witness fails:

The answer, at least that is what I thought, was simple: All VMs will remain running, or said differently, there’s no impact on vSAN. While doing the test, indeed the outcome I documented, which is also documented in the Stretched Clustering Guide and the PoC Guide was indeed the same, the VMs remain running. However, one of the things that was noticed is that when this situation occurs, and indeed the connection between Site A and the Witness is lost, the witness is somehow no longer part of the cluster, which is not what I would expect. The reason I would not expect this to happen is because if a second failure would occur, and for instance the ISL between Site A and Site B goes down, it would direclty impact all VMs. At least, that is what I assumed.

However, when I triggered that second failure and I disconnected the ISL between Site A and Site B, I saw the witness re-appearing again immidiately, I saw the witness objects going from “absent” to “active”, and more importantly, all VMs remained running. The reason this happens is fairly straight forward, when running a configuration like this vSAN has a “leader” and a “backup”, and they each run in a seperate fault domain. Both the leader and the backup need to be able to communicate with the Witness for it to be able to function correctly. If the connection between Site A and the Witness is gone, then either the leader or the backup can no longer communicate with the Witness and the Witness is taken out of the cluster.

So why does the Witness return for duty when the second failure is triggered? Well, when the second failure is triggered the leader is restarted in Site B (as Site A is deemed lost), and the backup is already running in Site B. As both the leader and the backup can communicate again with the witness, the witness returns for duty and so will all of the components automatically and instantly. Which means that even though the ISL has failed between Site A and B after the witness was taken out of the cluster, all VMs remain accessible as the witness is reintroduced instantly to ensure availability of the workload. Pretty cool!  (Thanks to vSAN engineering for providing these insights on why this happens!)
Memory Tiering… Say what?!

Duncan Epping · Jun 14, 2024 ·

Recently I presented a keynote at the Belgium VMUG, the topic was Innovation at VMware by Broadcom, but I guess I should say Innovation at Broadcom to be more accurate. During the keynote I briefly went over the process and the various types of innovation and what this can lead to. During the session, I discussed three projects, namely vSAN ESA, the Distributed Services Engine, and something which is being worked on called: Memory Tiering.

Memory Tiering is a very interesting concept that was first publicly discussed at Explore (or VMworld I guess it was still. called) a few years ago as a potential future feature. You may ask yourself why anyone would want to tier memory, as the impact from a performance stance can be significant. There are various reasons to do so, one of them being the cost of memory. Another problem the industry is facing is the fact that memory capacity (and performance) has not grown at the same rate as CPU capacity, which has resulted in many environments being memory-bound, differently said the imbalance between CPU and memory has increased substantially. That’s why VMware started Project Capitola.

When Project Capitola was discussed most of the focus was on Intel Optane, and most of us know what happened to that. I guess some assumed that that would also result in Project Capitola, or memory tiering and memory pooling technology, being scrapped. This is most definitely not the case, VMware has gone full steam ahead and has been discussing the progress in public, although you need to know where to look. If you listen to that session it is clear that there are various efforts, that would allow customers to tier memory in various ways, one of them being of course the various CXL based solutions that are coming to market now/soon.

One of which is memory tiering via a CXL accelerator card, basically an FPGA that has the sole purpose of increasing memory capacity, offload memory tiering and accelerating certain functionality where memory is crucial like for instance vMotion. As mentioned in the SNIA session, using an accelerator card can lead to a 30% reduction in migration times. An accelerator card like this will also open up other opportunities, like pooling memory for instance, which is something customers have been asking for since we created the concept of a cluster. Being able to share compute resources across hosts. Just imagine, your VM can use memory capacity available on another host without having to move the VM. Yes, before anyone comments on this, I do realize that this will have a significant performance impact potentially.

That is of course where the VMware logic comes into play. At VMworld in 2021 when Project Capitola was presented, the team also shared the performance results of recent tests, and it showed that the performance degradation was around 10% when 50% of DRAM was used and 50% of Optane memory. I was watching the SNIA session, and this demo shows the true power of VMware vSphere, memory tiering, and acceleration (Project Peaberry as it is called). On average the performance degradation was around 10%, yet roughly 40% of virtual memory was accessed via the Peaberry accelerator. Do note that the tiering is completely transparent to the application, this works for all different types of workloads out there. The crucial part here to understand is that because the hypervisor is already responsible for memory management, it knows which pages are hot and which pages are cold, that also means it can determine which pages it can move to a different tier while maintaining performance.

Anyway, I cannot reveal too much about what may, or may not, be coming in the future. What I can promise though is that I will make sure to write a blog as soon as I am allowed to talk about more details publicly, and I will probably also record a podcast with the product manager(s) when the time is there, so stay tuned!

Do I need 2 isolation addresses with a (vSAN) stretched cluster for vSphere HA?

Duncan Epping · Sep 27, 2023 ·

This question has come up multiple times now, so I figured I would write a quick post about it, do you need 2 isolation addresses with a (vSAN) stretched cluster for vSphere HA? This question comes up as the documentation has best practices around the configuration of HA isolation addresses for stretched clusters. The documentation (both for vSAN as well as traditional stretched storage) states that you need to have two reliable addresses, one in each location.

Now I have had the above question multiple times as some folks have mentioned that they can use a Gateway Address with Cisco ACI which would still be accessible in both locations even if there’s a partition due to for instance an ISL failure. If that is the case, and the IP address is indeed available in both locations during those types of failure scenarios then it would suffice to use a single IP address as your isolation address.

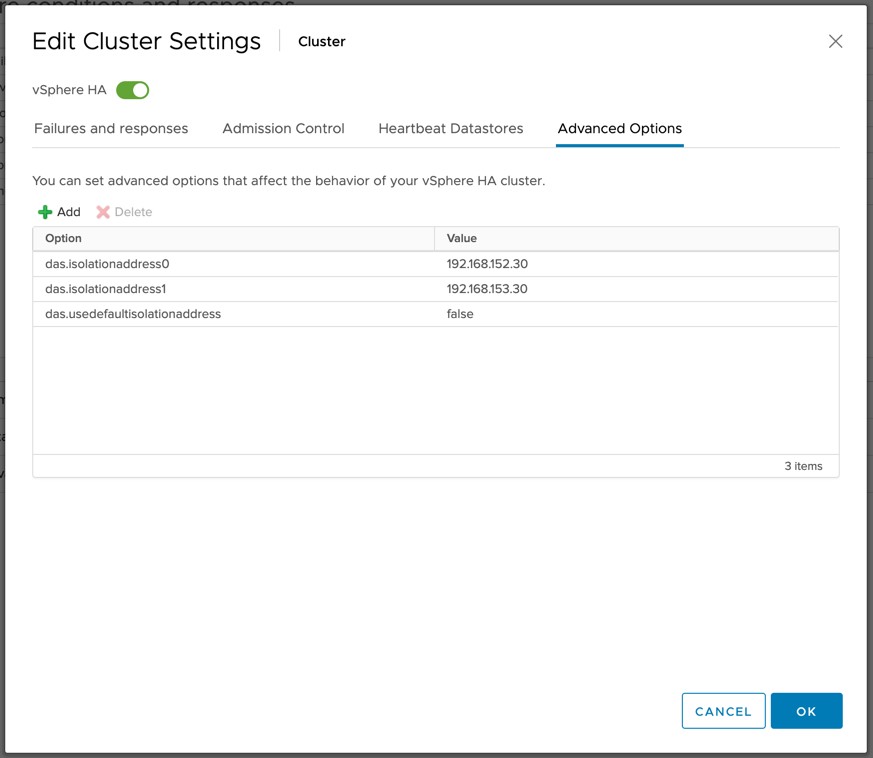
You will however need to make sure that the IP address is reachable over the vSAN network when using vSAN as your stretched storage platform. (When vSAN is enabled vSphere HA uses the vSAN network for communications.) If it is reachable you can simply define the isolation address by setting the advanced setting “das.isolationaddress0”. It is also recommended to disable the use of the default gate of the management network by setting “das.usedefaultisolationaddress” to false for vSAN based environments.

I have requested the vSAN stretched clustering documentation to be updated to reflect this.

vSphere 8.0 U2 and vSAN 8.0 U2 just shipped, learn all about it here!

Duncan Epping · Sep 22, 2023 ·

vSphere 8.0 U2 and vSAN 8.0 U2 just shipped, and of course the Unexplored Territory Podcast has already covered this. If you want to learn all about it make sure to listen to the episode below. Or of course read the release notes (vCenter, ESXi, vSAN).

You can find the vSAN 8.0 U2 episode on Spotify (https://bit.ly/3QNjpFk), and Apple (https://bit.ly/3QPt7XL), as well as any other podcast app, or simply listed via the embedded player below!

You can find the vSphere 8.0 U2 episode on Spotify (https://bit.ly/3snOh5l), Apple (https://bit.ly/45lRK2Q), as well as any other podcast app, or simply listed via the embedded player below!

New book: VMware vSAN 8.0 U1 Express Storage Architecture Deep Dive!

Duncan Epping · Apr 27, 2023 ·

We already gave some hints on twitter, and during an episode of the Unexplored Territory podcast, but here it finally is… The new book, the VMware vSAN 8.0 U1 Express Storage Architecture Deep Dive! It has been a year since we released the vSAN 7.0 U3 Deep Dive book, and with this brand new vSAN architecture being introduced in vSAN 8.0 we figured it was time to do a full overhaul of the book as well. Mind you, this new book purely deals with the Express Storage Architecture, aka vSAN ESA. This also means that some of the features which are not supported by ESA are not discussed in this book, for that you will need to buy the vSAN 7.0 U3 Deep Dive book, which covers OSA. Another big change is that we brought in a third author, we asked our good friend Pete Koehler to contribute to the book. Pete had done reviews of previous books, and considering the amount of material he produced for VMware Tech Marketing for vSAN (and ESA specifically) it made a lot of sense to bring him in!

VMware’s vSAN has rapidly proven itself in environments ranging from hospitals to oil rigs to e-commerce platforms and is the market leader in the hyperconverged space. Along the way, the world of IT has rapidly changed, not just from a software point of view, but also from a hardware perspective. With vSAN 8.0 VMware brought a new architecture to market called vSAN Express Storage Architecture (ESA). This architecture is highly optimized for today’s world of datacenter resources, be it CPU, memory, networking, or NVMe based flash storage.

The authors of the vSAN Deep Dive have thoroughly updated their definitive guide to this transformative technology. Writing for vSphere administrators, architects, and consultants, Cormac Hogan, Duncan Epping , and Pete Koehler explain what vSAN ESA is, why the architecture has changed, what it now offers, and how to gain maximum value from it. The book offers expert insight into preparation, installation, configuration, policies, provisioning, clusters, architecture, and more. You’ll also find practical guidance for using all data services, stretched clusters, two-node configurations, and cloud-native storage services.

Although we pressed publish on Tuesday, sometimes it takes a while before the book is available in all Amazon stores, but it should just trickle down in the upcoming 24-48 hours. The book is priced at 9.99 USD for the ebook and 29.99 USD for a paper copy, and is sold through Amazon only. Get it while it is hot, and we would appreciate it if you would use our referral links and leave a review when you finish it. Thanks for the support, and we hope you will enjoy it!

  • paper – 29.99 USD
  • ebook – 9.99 USD

Of course, we also have the links to other major Amazon stores:

  • United Kingdom – ebook – paper
  • Germany – ebook – paper
  • Netherlands – ebook – paper
  • Canada – ebook – paper
  • France – ebook – paper
  • Spain – ebook – paper
  • India – ebook
  • Japan – ebook – paper
  • Italy – ebook – paper
  • Mexico – ebook
  • Australia – ebook – paper
  • Brazil – ebook
  • Or just do a search in your local amazon store!

  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 5
  • Page 6
  • Page 7
  • Page 8
  • Page 9
  • Interim pages omitted …
  • Page 11
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in