• Skip to primary navigation
  • Skip to main content
  • Skip to primary sidebar

Yellow Bricks

by Duncan Epping

  • Home
  • Unexplored Territory Podcast
  • HA Deepdive
  • ESXTOP
  • Stickers/Shirts
  • Privacy Policy
  • About
  • Show Search
Hide Search

BC-DR

Site Recovery Manager and MSCS

Duncan Epping · Jan 13, 2009 ·

When reading several SRM docs I was wondering if Microsoft Clustering was supported or not. I knew that in version 1.0 it wasn’t supported. When reading the Release Notes I noticed the following:

Full Support for RDM devices
SRM now provides full support for virtual machines that use raw disk mapping (RDM) devices. This enables support of several new configurations, including Microsoft Cluster Server. (Virtual machine templates cannot use RDM devices.)

Microsoft Clustering Services is supported as of Update 1. But you will need to keep in mind when creating your Recovery Plan that all nodes of the cluster will belong to the same Protection Group and can possibly  be started up or shutdown at the same time….. I haven’t configured SRM in combination with MSCS so far, if any of you has any tips/tricks let me know.
Site Recovery Manager is not about installing… Part II

Duncan Epping · Jan 12, 2009 ·

I’ve been playing around with Site Recovery Manager these last couple of days. Installing it was really easy and same goes for the basic configuration. I already wrote a blog about this topic a month ago or so but now I’ve experienced it myself. Most of the time during a Site Recover Manager project will be spent during the Plan & Design phase and writing documentation. I will just give you one example why. The following was taken from the SRM Course material:

Datastore Group
Replicated datastores containing the complete set of virtual machines that you want to protect with SRM

Protection Group
A group of virtual machines that are failed over together during test and recovery

For those who don’t know, there’s a one on one mapping between Datastore Groups and Protection Groups. So in other words, once you’ve mapped a Datastore Group to a Protection Group there’s no way of changing it without having to recreate the Protection Group.

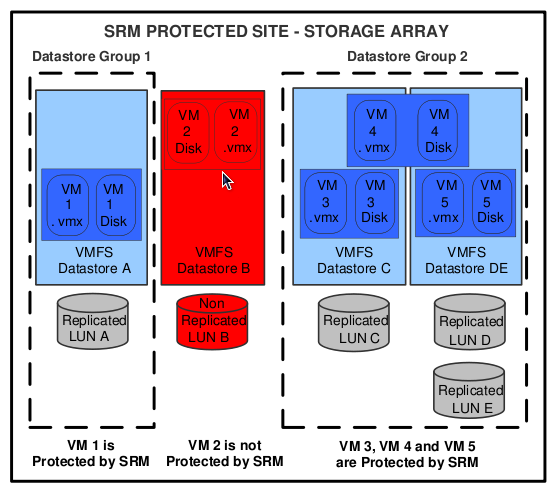
I think a picture says more than a 1000 words so I stole this one from the Evaluator Guide to clarify the relationship between datastore, Datastore Groups and Protection Groups:

Notice that there are multiple datastores in Datastore Group 2 because VM4 has disks in both datastores. So these datastores are joined into one Datastore Group. This Datastore Group will have a one to one relationship with a Protection Group. Keep in mind, this is really important: a Protection Group contains VM’s that are failed over together during test and recovery.

If you’ve got VM’s with multiple disks on multiple datastores with no logic in which disk is placed on which datastore you could and probably will end up with all datastores being member of the same Datastore Group. Being member of the same Datastore Group means being part of the same Protection Group. Being part of the same Protection Group will result in a less granular fail-over. It’s all or nothing in this case and I can imagine most companies would like to have some sort of tiering model in place or even better fail over services one at a time. (This doesn’t mean by the way that if you create multiple Protection Group that you can’t fail over everything at the same time, they can all be joined in a Recovery Plan)

Some might think that you would be able to randomly add disks to datastores after you finished configuring. This clearly isn’t the case. If you add a disk to a protected(!) VM the Datastore Group will be recomputed. In our situation this meant that all VM’s in the “Medium Priority” Protection Group were moved over to the “High Priority” Protection Group. This was caused by the fact that we added a disk to a “Medium Priority” VM and placed it on a “High Priority” datastore. As you can imagine this also causes your Recovery Plans to end up with a “warning”, you will need to reconfigure the moved VM’s before you can fail them over as part of your “High Priority” datastore. (Which probably wasn’t the desired strategy…)

When I was searching the internet for information on SRM I stumbled upon this article on the VMware Uptime blog by Lee Dilworth. I’ve taken the following from the “What we’ve learnt” post, which confirms what we’ve seen the last couple of days:

Datastore Group computation is triggered by the following events:

  • Existing VM is deleted or unregistered
  • VM is storage vmotioned to a different datastore
  • New disk is attached to VM on a datastore previously not used by the VM
  • New datastore is created
  • Existing datastore is expanded

So in other words, moving VM’s from one Datastore to another or creating a new disk on a different Datastore can cause problems because the Datastore Group computation will be re-run. Not only do you need to take virtual disk placement in consideration when configuring SRM, you will also need to be really careful when moving virtual disks. Documentation, Design and Planning is key here.

I would suggest documenting current disk placement before you even start implementing SRM, and given the results you might need to move disks around before you start with SRM. Make sure to check your documentation and design before randomly adding virtual disks when SRM has been implemented. Documenting your current disk placement can be done easily with the script that Hugo created this week by the way, and I would suggest to regularly create reports and save them.

Expect some more SRM stuff coming up over the next couple of weeks.

Health Check tools I use

Duncan Epping · Dec 18, 2008 ·

A few days ago Scott Lowe asked me which tools I use to deliver a health check engagement. A health check is a standard VMware PSO engagement, a VMware Consultant will be on site to check the status of your environment and will draw up a report.

I personally use the following tools:

  • Health Check script by A.Mikkelsen → for a quick overview of the current situation and setup, small files and easy to carry around, runs from the Service Console.
  • VMware Health Analyzer Appliance → A linux appliance that can connect to your VC/ESX and analyze log files. At this point in time it’s only available for VMware Employees or Partners with access to Partner Central.
  • Powershell: Report into MS Word → Alan Renouf created this great reporting powershell scripts. It dumps info into a word document. (And i’ve heard he’s also working on a Visio export)
  • Powershell: Health Check Script → Create an html report with datastore, cpu, memory and snapshot info… and more.
  • RVTools → Gives a quick overview of current VM setup like snapshots, memory, cpu etc.
  • Common sense → I hardly encounter really huge problems, mainly decreased availability cause of choices made during implementation / design phase without following VMware’s guidelines. Use common sense is the best advise in this case and read the best practice documents and VMware’s collection of pdf’s!
  • And when there are some disturbing errors in one of the various log files you have the option to run it through one of the many toolkits we internally have.

I’m not using the following tools actively during engagements because of licensing but they can be very usefull in your enviroment:

  • Replicate Datacenter Analyzer → Analyze your VI3 environment, I wrote an article a few weeks ago on RDA, click here
  • Veeam Monitor → Monitor your VI3 environment including performance graphs etc.
  • Veeam Reporter → A reporting tool, which will come in handy when documenting environments and comparing the current config to an old config.
  • Vizioncore vFoglight → Might come in handy when doing analyses of trends and pinpointing resource contention.
  • Tripwire Configcheck → Analyze the security of your VMware ESX environment. Check my blog post on Configcheck here.

Scripts, scripts, scripts… come and get them!

Duncan Epping · Dec 18, 2008 ·

I was just pointed out to this amazing topic on the VMTN Forums by William Lam and Tuan Duong. These guys created a whole bunch of scripts and decided to share them with the rest of the world:

My colleague (Tuan Duong) and I (William Lam) have been working on a virtualization/VDI deployment project over the last six months. The result of this work is a set of scripts that assist in provisioning and managing the server and lab environment for the Residential Networking Services (ResNet) at the University of California, Santa Barbara.

We took the approach of developing scripts that would be free in nature to support a variety of offerings that currently exist in the enterprise space. One such tool that we would like to share with the VMware community is our Linked Clones script that was developed at the beginning of the summer of 2008. This script functions similarly to the View Composer component in the recent release of VMware View 3 but with relatively relaxed requirements.

A description and more details of the Linked Clones script can be found at:

http://communities.vmware.com/docs/DOC-9020

Another script that complements the Linked Clone’s script is our custom management script “*my-vmware-cmd*” which can be found at:

http://communities.vmware.com/docs/DOC-9061

An example of our implementation of these scripts can be found at:

http://communities.vmware.com/docs/DOC-9201

We also have other scripts and resources that have been consolidated onto a webpage and would like to share it:

http://www.engineering.ucsb.edu/~duonglt/vmware/

We hope that the community finds some of these scripts to be useful in aiding VI administrators to manage their virtual infrastructure and look forward to any feedback that is provided.

Thanks
William lamw and Tuan tlduong

Check these scripts out if you’re looking for a linked clone solution on a non View Composer environment. Their website also contains a bunch of scripts, tips and tricks. One that really stands out is the RDM script, believe me this is a must have for your toolkit:

Download: rdm.sh – 11/03/08
Compatiable with: ESX 3.5+ and ESXi

This script is used to locate all virtual machines that have an RDM mapping and provides the VMs Name, Hard Disk label shown on the VIC/VC, Datastore, LUN UUID, HBA/LUN, Compatibility Mode (Phys/Virt), DiskMode and Capacity.

HA: who decides where a VM will be restarted?

Duncan Epping · Dec 15, 2008 ·

During the Dutch VMUG someone walked up to me and asked a question about High Availability. He read my article on Primary and Secondary nodes and was wondering who decided where and when VM would be restarted.

Let’s start with a short recap of the  “primary/secondary” article: “The first five servers that join the cluster will become a primary node, and the others that will join will become a secondary node. Secondary nodes send their state info to primary nodes and also contact the primary nodes for their heartbeat notification. Primary nodes replicate their data with the other primary nodes and also send their heartbeat to other primary nodes.”

The question was, when a fail-over needs to take place cause an isolation occurred who decides on which host a specific VM will be restarted. The obvious answer is one of the primaries. One of the primaries will be selected as the “fail-over coordinator”. The fail-over coordinator coordinates the restart of virtual machines on the remaining hosts. The coordinator takes restart priorities in account. Keep in mind, when two hosts fail at the same time it will handle the restart sequentially. In other words, restart the VM’s of the first failed host(taking restart priorities in account) and then restart the VM’s of the host that failed as second(again taking restart priorities in account). If the fail-over coordinator fails one of the primaries will take over.

By the way, this is another reason why you can only account for 4 host failures. You need at least 1 primary, this primary will be the fail-over coordinator. When the last primary dies….

  • « Go to Previous Page
  • Page 1
  • Interim pages omitted …
  • Page 56
  • Page 57
  • Page 58
  • Page 59
  • Page 60
  • Interim pages omitted …
  • Page 64
  • Go to Next Page »

Primary Sidebar

About the Author

Duncan Epping is a Chief Technologist and Distinguished Engineering Architect at Broadcom. Besides writing on Yellow-Bricks, Duncan is the co-author of the vSAN Deep Dive and the vSphere Clustering Deep Dive book series. Duncan is also the host of the Unexplored Territory Podcast.

Follow Us

  • X
  • Spotify
  • RSS Feed
  • LinkedIn

Recommended Book(s)

Also visit!

For the Dutch-speaking audience, make sure to visit RunNerd.nl to follow my running adventure, read shoe/gear/race reviews, and more!

Do you like Hardcore-Punk music? Follow my Spotify Playlist!

Do you like 80s music? I got you covered!

Copyright Yellow-Bricks.com © 2026 · Log in